A global brand. Forty markets. Some run as single countries, some as clusters.
And one big ambition: a single view of every customer, everywhere.
That’s usually how a Data 360 implementation (yes, the product we all still call Data Cloud half the time) starts its life on a whiteboard.
Cool, right?
But here’s the thing. The whiteboard version hides five decisions that get locked in early — and some of them are genuinely painful to undo later.
Salesforce has published a fair amount of guidance on this: architect decision guides, Trailhead modules and a fresh Flex Credits rate card. Read together, they tell a clearer story than any one of them alone.
So, let’s have a look.
Data 360 implementation in a nutshell
- Instances: as few as possible, but one per region where residency demands it.
- Data spaces: carve by region or market cluster, not by every country.
- MDM: Data 360 is a system of reference. Your MDM stays the system of record.
- Snowflake: ingest what you govern centrally, federate what changes often, share back what analysts need.
- Credits: unification is the expensive line on the rate card, by a long way. Design identity resolution like it’s a budget decision — because it is.
First, the building blocks
If you’ve delivered a single-market Data Cloud implementation before, most of this is familiar. What changes at global scale is how these pieces combine:
- Home org — the Salesforce org where your Data 360 instance is provisioned. Its region is the instance’s region.
- Companion orgs — other orgs connected through Data Cloud One. They can use shared data, but they can’t ingest or unify data themselves.
- Data spaces — logical partitions of data, metadata and processes inside one instance.
- Unified profile — the result of identity resolution: a linked view across sources, not a mastered record.
- Flex Credits — the consumption currency. Under this model, most processing is billed per million rows, with a different multiplier per usage type.
How many Data 360 instances do you actually need?
This is the first decision in any Data 360 implementation, and the hardest to reverse.
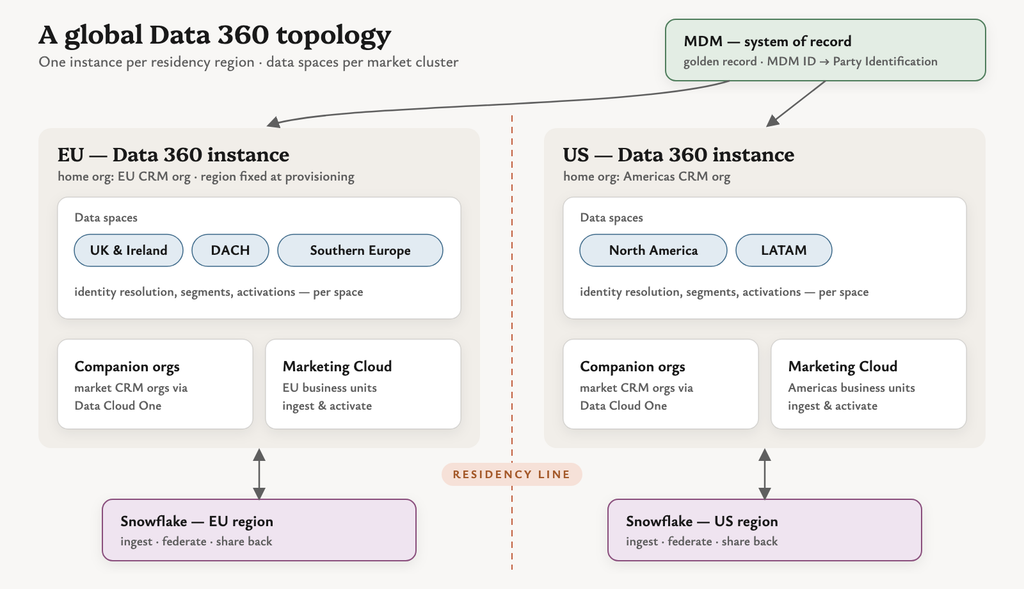
Salesforce’s Data 360 provisioning decision guide is clear: create “the least number of Data 360 instances as possible, ideally by using Data Cloud One”. Multiple instances make sense “only… when required by compliance, residency, or organizational autonomy”.
And the region? It’s fixed at provisioning, inherited from the home org. Changing the home org later is described as “difficult and disruptive”.
Now here’s the part people often miss. Trailhead says it plainly: “Data spaces don’t solve data residency needs.”
So if your EU customer data must stay in the EU, that’s a separate instance, not a separate data space.
Where the work runs: in the home org’s region. Hard to change later: home org, region, instance count. Watch-out: zero-copy federation is region-sensitive too — a Snowflake account in the EU pairs naturally with an EU instance.
If a client asked me tomorrow, I’d start with one question: which markets legally can’t share an instance? That list sets the instance count. Everything else is preference.
Example scenarios
- A retailer with strict EU residency commitments and a US business: one EU instance, one US instance, each unifying its own region.
- A B2B manufacturer with no residency constraints across 30 markets: one instance, with the regional CRM orgs connected as companion orgs.
Carving up markets with data spaces
Inside an instance, data spaces do the market separation. Salesforce describes them as a way to “segregate data, metadata, and processes by categories such as brand, region, or department”.
Segments, calculated insights and activations all run in the context of a data space. Each data space gets its own permission set, so market teams only see what they should.
The tempting move in a multi-market Data 360 implementation is one data space per country.
Well… you can try. But the number of data spaces depends on your licences, identity resolution rulesets are configured per data space, and ruleset runs are throttled per data space too. Forty countries means forty rulesets to design, test and pay for.
What it does: separates data, metadata, permissions and processing by market. Good grain: a region or a cluster of markets that share processes, languages or teams. Watch-out: a customer who appears in two data spaces is unified separately in each. Cross-market unification and strict separation pull in opposite directions.
Example scenarios
- A beauty brand groups its 12 EMEA markets into three data spaces (UK & Ireland, DACH, Southern Europe), each with its own marketing team.
- A travel company keeps one global data space for loyalty members who book across countries, plus a separate space for a sub-brand.
Data 360 and your MDM: reference, not record
This one comes up in nearly every enterprise Data 360 implementation.
“Once Data 360 is live, we won’t need the MDM.”
But the documentation gives us more nuance than that. Salesforce says identity resolution “creates complete, actionable views of your customers but doesn’t create golden records and isn’t a master data management (MDM) system“. Unified profiles “act as a system of reference.”
That’s an important distinction.
So the sensible pattern is to let each do its job:
- MDM owns the golden record, survivorship and stewardship.
- Data 360 ingests the MDM’s mastered IDs and uses them as a match key. The Party Identification rule does exactly this — an exact match on identification number, name and type.
- Unified profiles then stitch in everything the MDM doesn’t hold: engagement, web, commerce and app behaviour.
Integration routes: Informatica (now part of Salesforce) offers a Data 360 connector and has announced MDM integration with Data 360; MuleSoft’s Data Cloud connector can stream records through the Ingestion API. Watch-out: I’d be careful about writing the unified profile ID back into the MDM as if it were a master key. Unification is rule-driven, so profiles can merge or split when rules or data change. Keep the MDM ID as the durable key.
Example scenarios
- An insurer’s MDM holds one party ID per policyholder across 15 countries; Data 360 uses it as the primary match rule, with email and phone as fallbacks.
- A brand without an MDM uses fuzzy name plus exact normalised email — and accepts that this is a system of reference, not a mastered record.
Snowflake: ingest, federate or share?
If your global data team already lives in Snowflake, your Data 360 implementation gets three ways to work with it. I covered the mechanics in my zero copy trade-offs post, so here’s the multi-market lens.
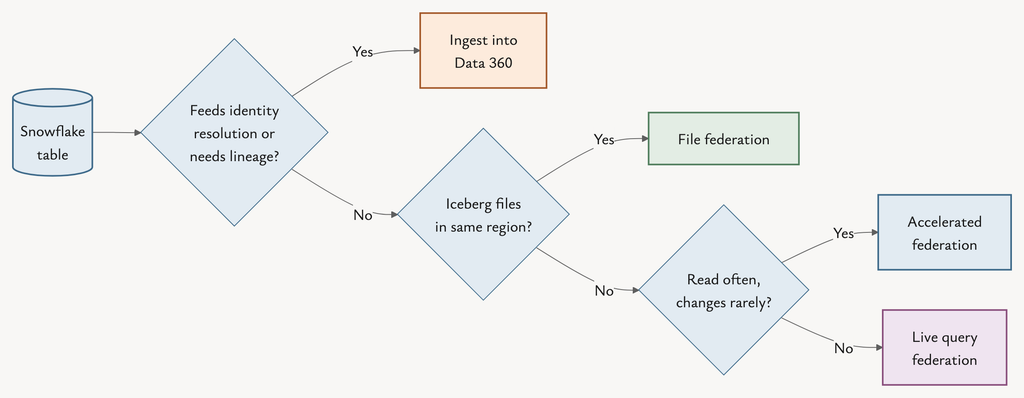
Salesforce’s interoperability decision guide gives the rule of thumb: ingest data that needs central governance, lineage or compliance; federate when governance at the source is acceptable.
- Ingest — copy into Data 360. Best for identity data that feeds unification.
- Live query federation — Data 360 queries Snowflake in place. Compute runs on Snowflake.
- Accelerated (cached) federation — Data 360 keeps a cached copy, refreshed between 15 minutes and 7 days. The guide notes incremental refresh “supports upserts only”, so deletions need a periodic full refresh.
- Share out — Data 360 objects appear in Snowflake for analysts. Salesforce’s latest Snowflake update describes them as native Iceberg tables.
Watch-out: Snowflake’s documentation notes you can’t share an external data lake object, or a DMO mapped to one, back out. Federated data doesn’t round-trip.
And here’s the interesting part for global brands: the guide says same-region file federation on AWS consumes no credits for the rows accessed, while cross-region does. Region alignment between Snowflake and each Data 360 instance is a cost decision, not just a latency one.
Example scenarios
- Ten years of order history in Snowflake, used for lifetime-value segments: federate with acceleration on a daily refresh.
- Customer master data from the MDM, landed in Snowflake first: ingest it, because it drives identity resolution.
Where Data 360 credits really go
Now things get a little more interesting.
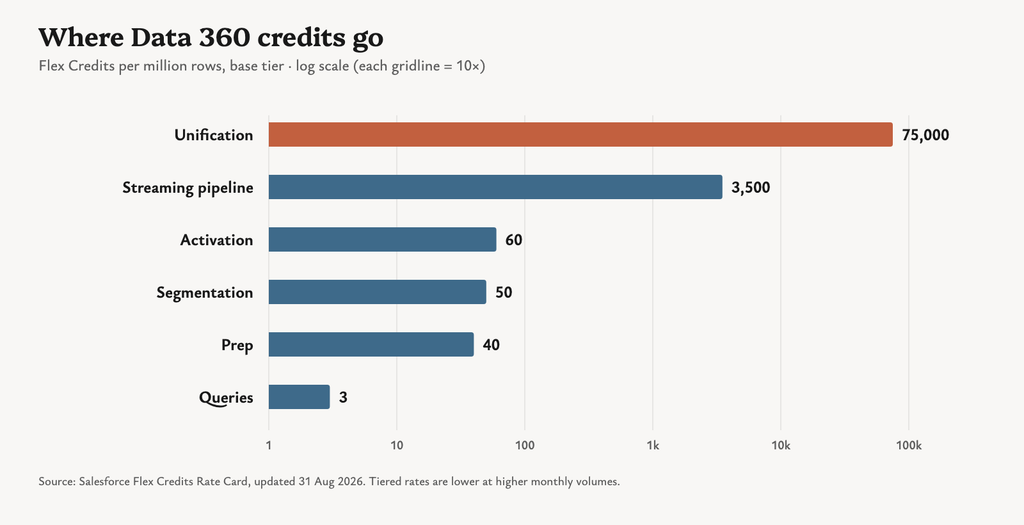
The Flex Credits rate card (updated 31 August 2026) prices most work per million rows, with a multiplier per usage type. At the base tier:
- Unification: 75,000 credits per million rows
- Streaming pipeline: 3,500
- Activation: 60
- Segmentation: 50
- Prep: 40
- Queries: 3
Wow — unification costs 1,250 times more per row than activation.
So the instinct to count activations first is understandable, but the rate card points somewhere else entirely. Identity resolution design is where a Data 360 implementation wins or loses on cost.
A few patterns follow from that:
- Unify only the profiles you’ll use. Billing is on rows processed, not on unified profile count. Filter dormant, test and duplicate records before they reach identity resolution — Trailhead’s own example is ingesting only profiles active in the last year.
- Freeze rulesets before go-live. A Salesforce architect writing on the Salesforce blog notes that changing a ruleset, match rule or reconciliation rule “triggers a full reprocessing of every source profile”. Iterate in a sandbox on a sample, not in production on 80 million rows.
- Batch by default, stream by exception. Streaming pipelines cost 3,500 per million rows against 40 for prep. Most markets don’t need second-by-second freshness.
- Match refresh cadence to change. Hourly is 24 times daily. Segments, insights and transforms should refresh as often as their inputs actually change.
- Watch federated segments. Without acceleration, every segment preview, refresh and activation runs a new live query — and Salesforce’s credit guidance for federation bills on rows scanned, even ones filtered out.
- Use the tiers. Multipliers drop as monthly usage per type grows, and sandbox has its own rate. Plan builds and backfills with that in mind.
- Consider the profile models. The Data 360 pricing page also offers per-profile pricing that “un-meters the usage types used to form unified profiles”. For very large, stable populations, that might change the maths.
Monitoring: Digital Wallet shows consumption by usage type in near real time; the monthly statement remains the source of truth.
Example scenarios
- A brand with 60 million source records cuts unification volume by a third by excluding contacts with no activity in three years.
- A market team switches abandoned-basket segments from hourly to every four hours after seeing basket data only lands four times a day anyway.
Data 360 implementation decisions at a glance
| Decision | Options | Choose when | Credit impact |
|---|---|---|---|
| Instances | One global vs one per region | Residency or compliance requires separation | Duplicate pipelines and unification per instance |
| Data spaces | Per country vs per market cluster | Teams, processes and consent rules align | Rulesets and runs multiply per space |
| MDM | Data 360 as master vs MDM ID as match key | An MDM already masters customers | Exact match keys keep unification lean |
| Snowflake | Ingest, live query, accelerated, share | Governance vs freshness vs volume | Live: per query. Cached: per refresh |
| Freshness | Streaming vs batch | Use case truly needs real time | Streaming costs far more per row |
So what should we actually take away from all this?
Here are the five questions I’d bring to the first Data 360 implementation workshop.
1. Which markets legally can’t share an instance?
That answer sets your instance count and your home org regions. Data spaces won’t fix it later.
2. What’s the right grain for a data space?
Usually a region or market cluster with shared teams and processes — not every flag on the map.
3. Who owns the golden record?
If you have an MDM, let it keep that job. Feed its ID into Party Identification and treat unified profiles as a system of reference.
4. Where does each Snowflake table belong?
Identity data in, large behavioural history federated, and analyst-facing data shared out — with regions aligned.
5. How many rows will identity resolution actually process?
Estimate it early in your Data 360 implementation, before you size the contract. It’s the line that dominates the bill.
The bigger picture
A global Data 360 implementation isn’t really a technical rollout. It’s a set of early commitments about geography, ownership and cost.
The better question isn’t:
“How do we get one view of every customer?”
It’s:
“Which customers need to be unified, where are they allowed to live, and how often does that view need to change?”
Answer those three and the architecture — and the bill — mostly design themselves.
The real traps aren’t in the features. They’re buried in the first workshop.
If you’re weighing up Snowflake specifically, my post on Data Cloud zero copy trade-offs goes deeper. And if you’re planning a multi-market rollout, I’m always happy to compare notes.