Category: Technologies

  • Data 360 for global brands: buried traps

    Data 360 for global brands: buried traps

    A global brand. Forty markets. Some run as single countries, some as clusters.

    And one big ambition: a single view of every customer, everywhere.

    That’s usually how a Data 360 implementation (yes, the product we all still call Data Cloud half the time) starts its life on a whiteboard.

    Cool, right?

    But here’s the thing. The whiteboard version hides five decisions that get locked in early — and some of them are genuinely painful to undo later.

    Salesforce has published a fair amount of guidance on this: architect decision guides, Trailhead modules and a fresh Flex Credits rate card. Read together, they tell a clearer story than any one of them alone.

    So, let’s have a look.

    Data 360 implementation in a nutshell

    • Instances: as few as possible, but one per region where residency demands it.
    • Data spaces: carve by region or market cluster, not by every country.
    • MDM: Data 360 is a system of reference. Your MDM stays the system of record.
    • Snowflake: ingest what you govern centrally, federate what changes often, share back what analysts need.
    • Credits: unification is the expensive line on the rate card, by a long way. Design identity resolution like it’s a budget decision — because it is.

    First, the building blocks

    If you’ve delivered a single-market Data Cloud implementation before, most of this is familiar. What changes at global scale is how these pieces combine:

    • Home org — the Salesforce org where your Data 360 instance is provisioned. Its region is the instance’s region.
    • Companion orgs — other orgs connected through Data Cloud One. They can use shared data, but they can’t ingest or unify data themselves.
    • Data spaces — logical partitions of data, metadata and processes inside one instance.
    • Unified profile — the result of identity resolution: a linked view across sources, not a mastered record.
    • Flex Credits — the consumption currency. Under this model, most processing is billed per million rows, with a different multiplier per usage type.

    How many Data 360 instances do you actually need?

    This is the first decision in any Data 360 implementation, and the hardest to reverse.

    Salesforce’s Data 360 provisioning decision guide is clear: create “the least number of Data 360 instances as possible, ideally by using Data Cloud One”. Multiple instances make sense “only… when required by compliance, residency, or organizational autonomy”.

    And the region? It’s fixed at provisioning, inherited from the home org. Changing the home org later is described as “difficult and disruptive”.

    Now here’s the part people often miss. Trailhead says it plainly: “Data spaces don’t solve data residency needs.”

    So if your EU customer data must stay in the EU, that’s a separate instance, not a separate data space.

    Where the work runs: in the home org’s region. Hard to change later: home org, region, instance count. Watch-out: zero-copy federation is region-sensitive too — a Snowflake account in the EU pairs naturally with an EU instance.

    If a client asked me tomorrow, I’d start with one question: which markets legally can’t share an instance? That list sets the instance count. Everything else is preference.

    Example scenarios

    • A retailer with strict EU residency commitments and a US business: one EU instance, one US instance, each unifying its own region.
    • A B2B manufacturer with no residency constraints across 30 markets: one instance, with the regional CRM orgs connected as companion orgs.
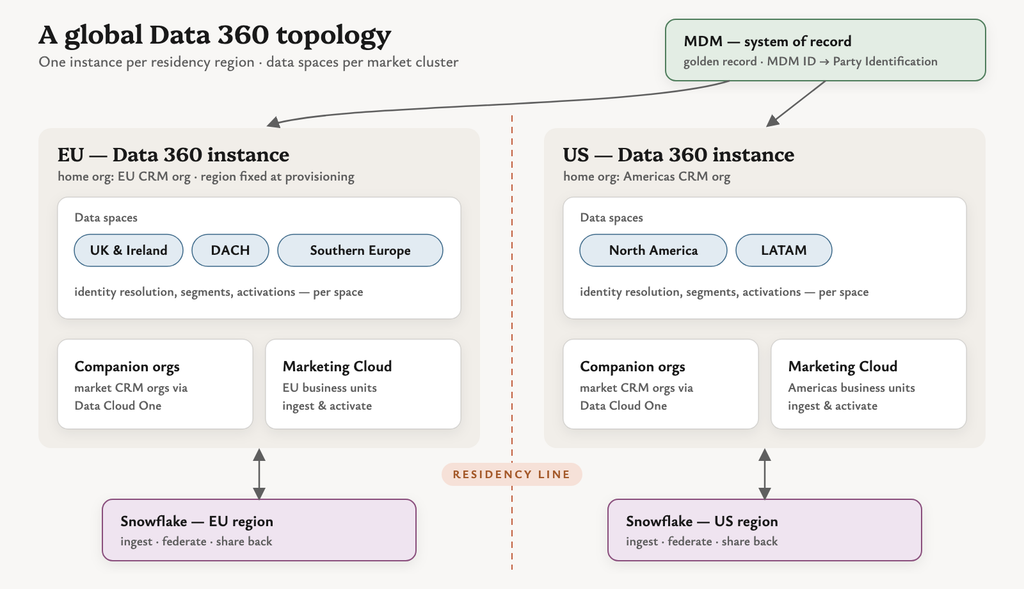
    Data 360 implementation topology with regional instances, market data spaces, companion orgs, MDM and Snowflake

    Carving up markets with data spaces

    Inside an instance, data spaces do the market separation. Salesforce describes them as a way to “segregate data, metadata, and processes by categories such as brand, region, or department”.

    Segments, calculated insights and activations all run in the context of a data space. Each data space gets its own permission set, so market teams only see what they should.

    The tempting move in a multi-market Data 360 implementation is one data space per country.

    Well… you can try. But the number of data spaces depends on your licences, identity resolution rulesets are configured per data space, and ruleset runs are throttled per data space too. Forty countries means forty rulesets to design, test and pay for.

    What it does: separates data, metadata, permissions and processing by market. Good grain: a region or a cluster of markets that share processes, languages or teams. Watch-out: a customer who appears in two data spaces is unified separately in each. Cross-market unification and strict separation pull in opposite directions.

    Example scenarios

    • A beauty brand groups its 12 EMEA markets into three data spaces (UK & Ireland, DACH, Southern Europe), each with its own marketing team.
    • A travel company keeps one global data space for loyalty members who book across countries, plus a separate space for a sub-brand.

    Data 360 and your MDM: reference, not record

    This one comes up in nearly every enterprise Data 360 implementation.

    “Once Data 360 is live, we won’t need the MDM.”

    But the documentation gives us more nuance than that. Salesforce says identity resolution “creates complete, actionable views of your customers but doesn’t create golden records and isn’t a master data management (MDM) system“. Unified profiles “act as a system of reference.”

    That’s an important distinction.

    So the sensible pattern is to let each do its job:

    • MDM owns the golden record, survivorship and stewardship.
    • Data 360 ingests the MDM’s mastered IDs and uses them as a match key. The Party Identification rule does exactly this — an exact match on identification number, name and type.
    • Unified profiles then stitch in everything the MDM doesn’t hold: engagement, web, commerce and app behaviour.

    Integration routes: Informatica (now part of Salesforce) offers a Data 360 connector and has announced MDM integration with Data 360; MuleSoft’s Data Cloud connector can stream records through the Ingestion API. Watch-out: I’d be careful about writing the unified profile ID back into the MDM as if it were a master key. Unification is rule-driven, so profiles can merge or split when rules or data change. Keep the MDM ID as the durable key.

    Example scenarios

    • An insurer’s MDM holds one party ID per policyholder across 15 countries; Data 360 uses it as the primary match rule, with email and phone as fallbacks.
    • A brand without an MDM uses fuzzy name plus exact normalised email — and accepts that this is a system of reference, not a mastered record.

    Snowflake: ingest, federate or share?

    If your global data team already lives in Snowflake, your Data 360 implementation gets three ways to work with it. I covered the mechanics in my zero copy trade-offs post, so here’s the multi-market lens.

    Salesforce’s interoperability decision guide gives the rule of thumb: ingest data that needs central governance, lineage or compliance; federate when governance at the source is acceptable.

    • Ingest — copy into Data 360. Best for identity data that feeds unification.
    • Live query federation — Data 360 queries Snowflake in place. Compute runs on Snowflake.
    • Accelerated (cached) federation — Data 360 keeps a cached copy, refreshed between 15 minutes and 7 days. The guide notes incremental refresh “supports upserts only”, so deletions need a periodic full refresh.
    • Share out — Data 360 objects appear in Snowflake for analysts. Salesforce’s latest Snowflake update describes them as native Iceberg tables.

    Watch-out: Snowflake’s documentation notes you can’t share an external data lake object, or a DMO mapped to one, back out. Federated data doesn’t round-trip.

    And here’s the interesting part for global brands: the guide says same-region file federation on AWS consumes no credits for the rows accessed, while cross-region does. Region alignment between Snowflake and each Data 360 instance is a cost decision, not just a latency one.

    Example scenarios

    • Ten years of order history in Snowflake, used for lifetime-value segments: federate with acceleration on a daily refresh.
    • Customer master data from the MDM, landed in Snowflake first: ingest it, because it drives identity resolution.
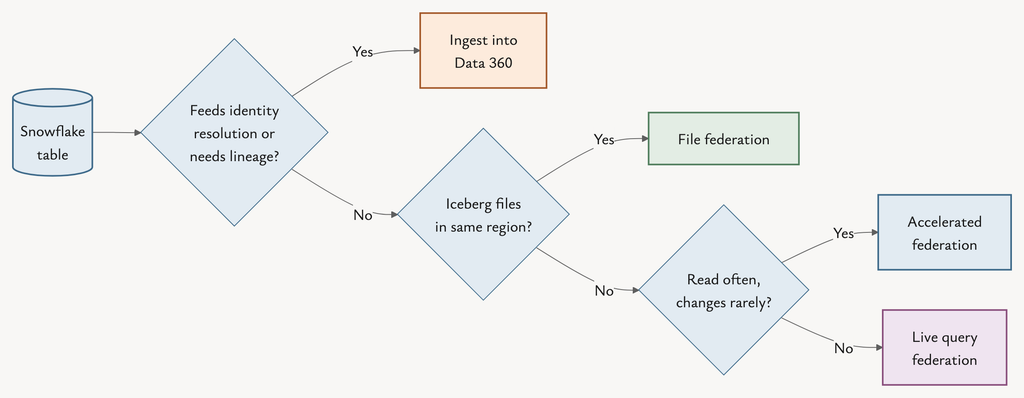
    Decision flow for Snowflake data in a Data 360 implementation: ingest, live query, accelerated federation or file federation

    Where Data 360 credits really go

    Now things get a little more interesting.

    The Flex Credits rate card (updated 31 August 2026) prices most work per million rows, with a multiplier per usage type. At the base tier:

    • Unification: 75,000 credits per million rows
    • Streaming pipeline: 3,500
    • Activation: 60
    • Segmentation: 50
    • Prep: 40
    • Queries: 3

    Wow — unification costs 1,250 times more per row than activation.

    So the instinct to count activations first is understandable, but the rate card points somewhere else entirely. Identity resolution design is where a Data 360 implementation wins or loses on cost.
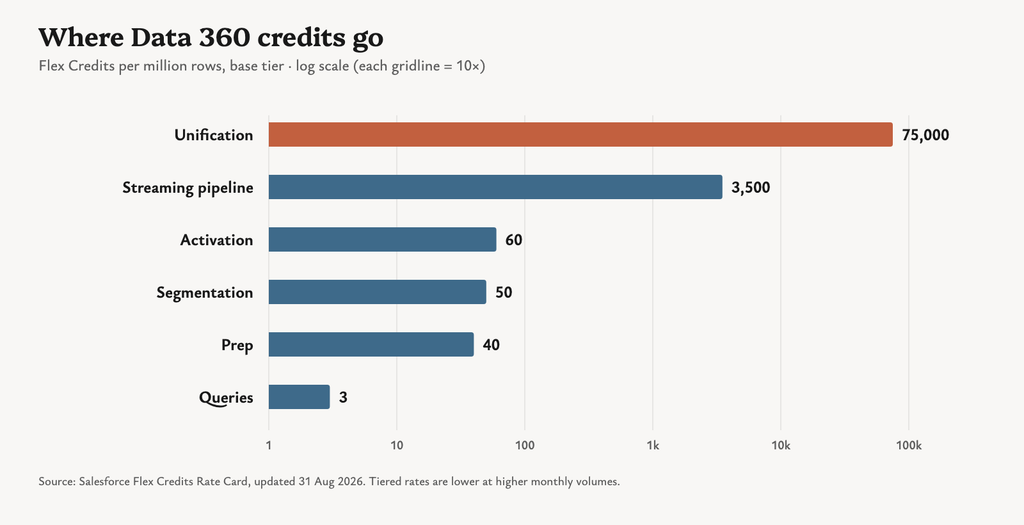
    Data 360 Flex Credits multipliers per million rows, showing unification far above other usage types

    A few patterns follow from that:

    • Unify only the profiles you’ll use. Billing is on rows processed, not on unified profile count. Filter dormant, test and duplicate records before they reach identity resolution — Trailhead’s own example is ingesting only profiles active in the last year.
    • Freeze rulesets before go-live. A Salesforce architect writing on the Salesforce blog notes that changing a ruleset, match rule or reconciliation rule “triggers a full reprocessing of every source profile”. Iterate in a sandbox on a sample, not in production on 80 million rows.
    • Batch by default, stream by exception. Streaming pipelines cost 3,500 per million rows against 40 for prep. Most markets don’t need second-by-second freshness.
    • Match refresh cadence to change. Hourly is 24 times daily. Segments, insights and transforms should refresh as often as their inputs actually change.
    • Watch federated segments. Without acceleration, every segment preview, refresh and activation runs a new live query — and Salesforce’s credit guidance for federation bills on rows scanned, even ones filtered out.
    • Use the tiers. Multipliers drop as monthly usage per type grows, and sandbox has its own rate. Plan builds and backfills with that in mind.
    • Consider the profile models. The Data 360 pricing page also offers per-profile pricing that “un-meters the usage types used to form unified profiles”. For very large, stable populations, that might change the maths.

    Monitoring: Digital Wallet shows consumption by usage type in near real time; the monthly statement remains the source of truth.

    Example scenarios

    • A brand with 60 million source records cuts unification volume by a third by excluding contacts with no activity in three years.
    • A market team switches abandoned-basket segments from hourly to every four hours after seeing basket data only lands four times a day anyway.

    Data 360 implementation decisions at a glance

    DecisionOptionsChoose whenCredit impact
    InstancesOne global vs one per regionResidency or compliance requires separationDuplicate pipelines and unification per instance
    Data spacesPer country vs per market clusterTeams, processes and consent rules alignRulesets and runs multiply per space
    MDMData 360 as master vs MDM ID as match keyAn MDM already masters customersExact match keys keep unification lean
    SnowflakeIngest, live query, accelerated, shareGovernance vs freshness vs volumeLive: per query. Cached: per refresh
    FreshnessStreaming vs batchUse case truly needs real timeStreaming costs far more per row

    So what should we actually take away from all this?

    Here are the five questions I’d bring to the first Data 360 implementation workshop.

    1. Which markets legally can’t share an instance?

    That answer sets your instance count and your home org regions. Data spaces won’t fix it later.

    2. What’s the right grain for a data space?

    Usually a region or market cluster with shared teams and processes — not every flag on the map.

    3. Who owns the golden record?

    If you have an MDM, let it keep that job. Feed its ID into Party Identification and treat unified profiles as a system of reference.

    4. Where does each Snowflake table belong?

    Identity data in, large behavioural history federated, and analyst-facing data shared out — with regions aligned.

    5. How many rows will identity resolution actually process?

    Estimate it early in your Data 360 implementation, before you size the contract. It’s the line that dominates the bill.

    The bigger picture

    A global Data 360 implementation isn’t really a technical rollout. It’s a set of early commitments about geography, ownership and cost.

    The better question isn’t:

    “How do we get one view of every customer?”

    It’s:

    “Which customers need to be unified, where are they allowed to live, and how often does that view need to change?”

    Answer those three and the architecture — and the bill — mostly design themselves.

    The real traps aren’t in the features. They’re buried in the first workshop.


    If you’re weighing up Snowflake specifically, my post on Data Cloud zero copy trade-offs goes deeper. And if you’re planning a multi-market rollout, I’m always happy to compare notes.
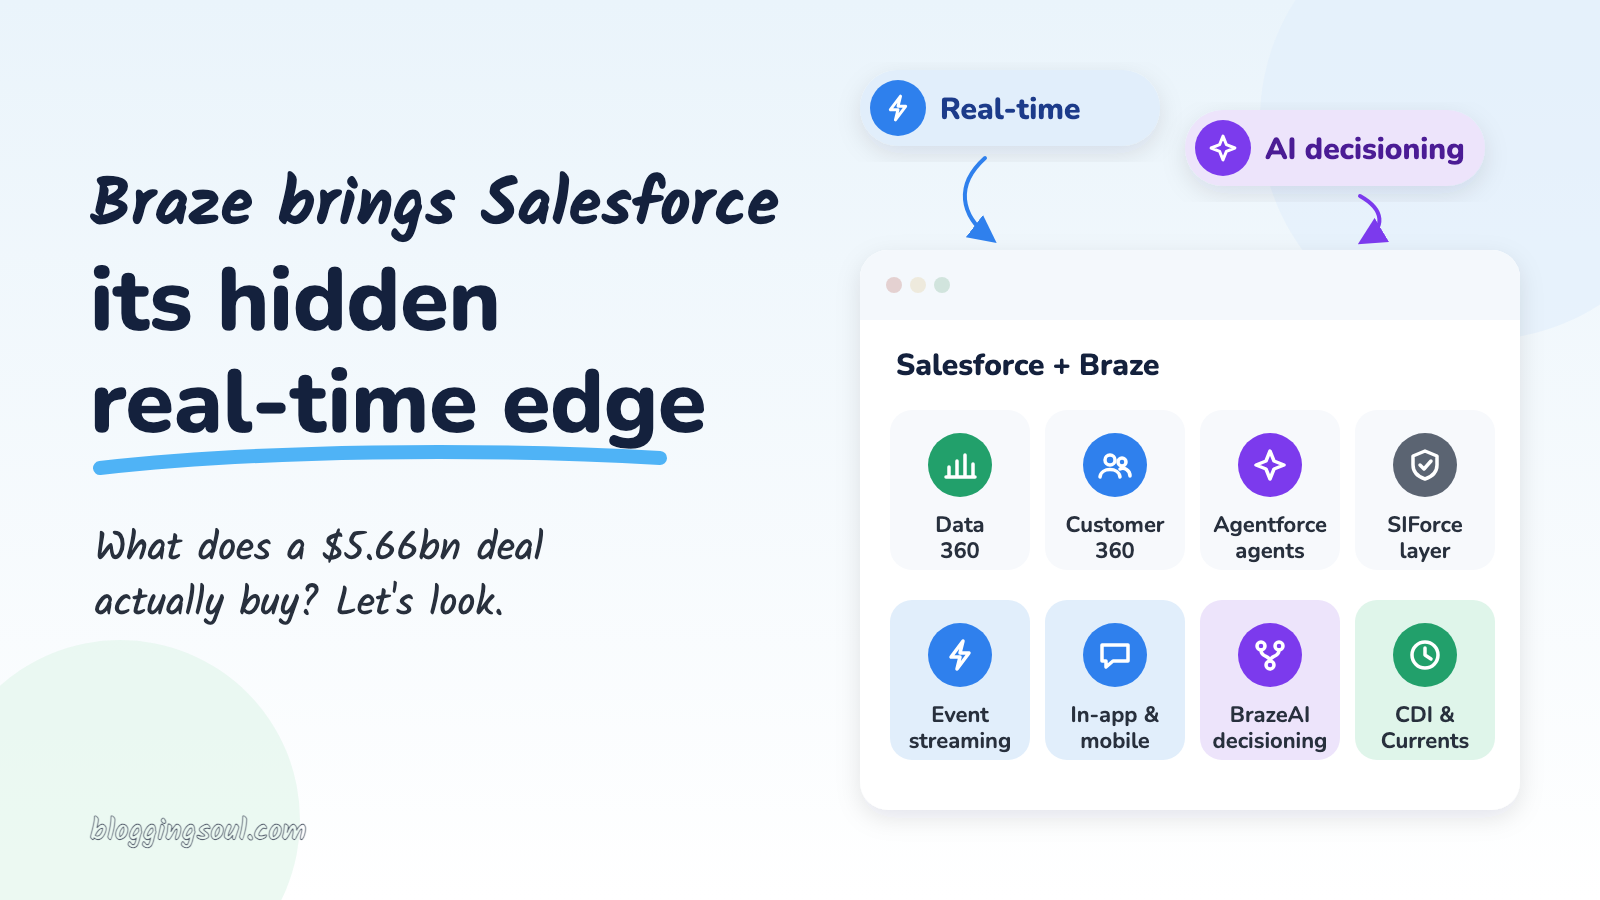
  • Braze brings Salesforce its hidden real-time edge

    Braze brings Salesforce its hidden real-time edge

    Salesforce is buying Braze.

    On 20 October, Salesforce announced it had signed an agreement to acquire Braze for roughly $5.66 billion in enterprise value, or $47.50 in cash per share.

    Cool, right?

    The first reaction I saw in most feeds was a version of the same thing:

    “Another marketing platform? Salesforce already has Marketing Cloud.”

    Fair question. But it’s not the most useful one.

    The better question about the Braze Salesforce deal is this: what does Braze do well that most of us find hard to do in the Salesforce stack today, and where would it plug in?

    Salesforce’s press release gives us a surprising amount of detail on that. And Braze’s own documentation fills in the rest.

    So, let’s have a look.

    The Braze Salesforce deal in a nutshell

    • The acquisition: ~$5.66bn enterprise value, $47.50 cash per Braze Class A share.
    • Timing: expected to close in Salesforce’s fiscal year 2028, subject to Braze shareholder and regulatory approval.
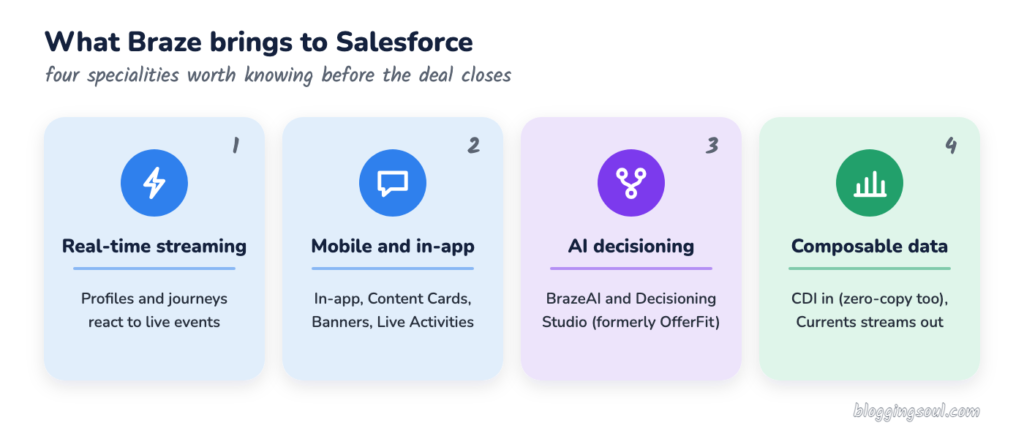
    • Specialities
      1. Real-time, event-streaming engagement
      2. Deep mobile and in-app channels
      3. AI decisioning across content, offers, channels and timing
      4. composable data plumbing, in from the warehouse and back out again
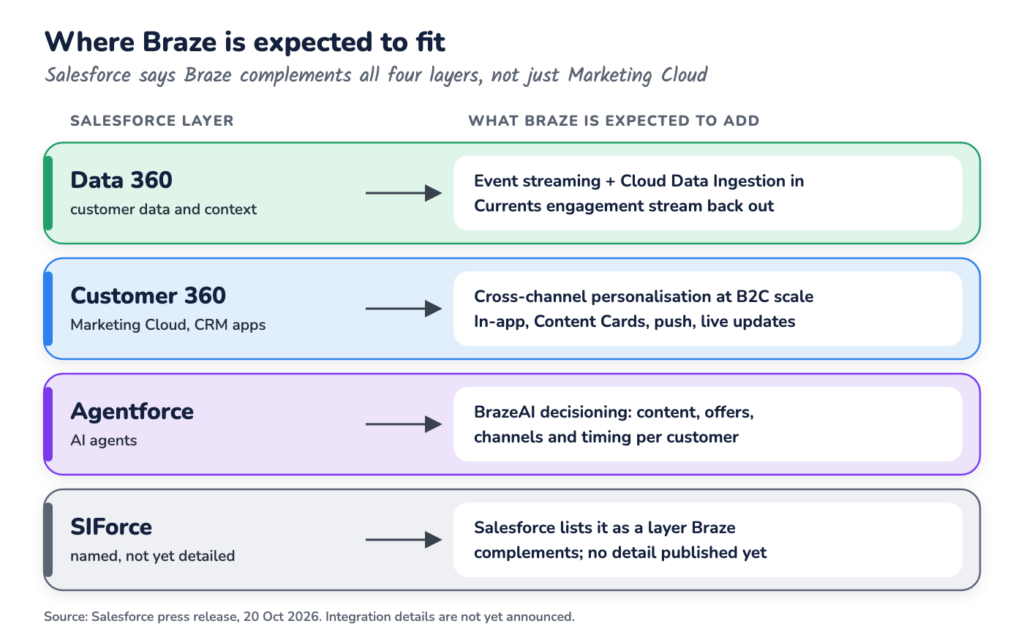
    • The pitch: Braze is expected to complement all four layers of Salesforce’s architecture, not just Marketing Cloud.
    Four Braze specialities in the Braze Salesforce deal: real-time streaming, mobile and in-app, AI decisioning, composable data

    First, what is Braze, and how is it different?

    If you’ve spent your career in Marketing Cloud Engagement, Braze can look familiar at first glance. Journeys, segments, email, SMS, push.

    But the design underneath is different. A few terms help:

    • Event streaming — customer behaviour (an app open, a basket update, a payment) flows in continuously and can change a profile or a journey within moments, rather than waiting for the next scheduled import.
    • Canvas — Braze’s journey builder. Roughly the equivalent of Journey Builder, but designed around those live events.
    • BrazeAI — the umbrella for Braze’s AI features, including Operator, agents, Intelligent Timing, Intelligent Channel and Decisioning Studio.
    • Currents — Braze’s outbound stream of engagement events (sends, opens, clicks and so on) to warehouses and other tools.

    Salesforce describes Braze’s architecture as “cloud-native, event-streaming… optimized for high-volume, real-time B2C engagement”, powering “trillions of messages and journey actions each year”.

    That’s the key distinction, and it’s the lens I’d use for the whole Braze Salesforce story. Some platforms are built around the campaign. Some are built around the moment.

    1. Real-time, event-streaming engagement

    This is the headline speciality in the Braze Salesforce deal, and the one Salesforce leads with.

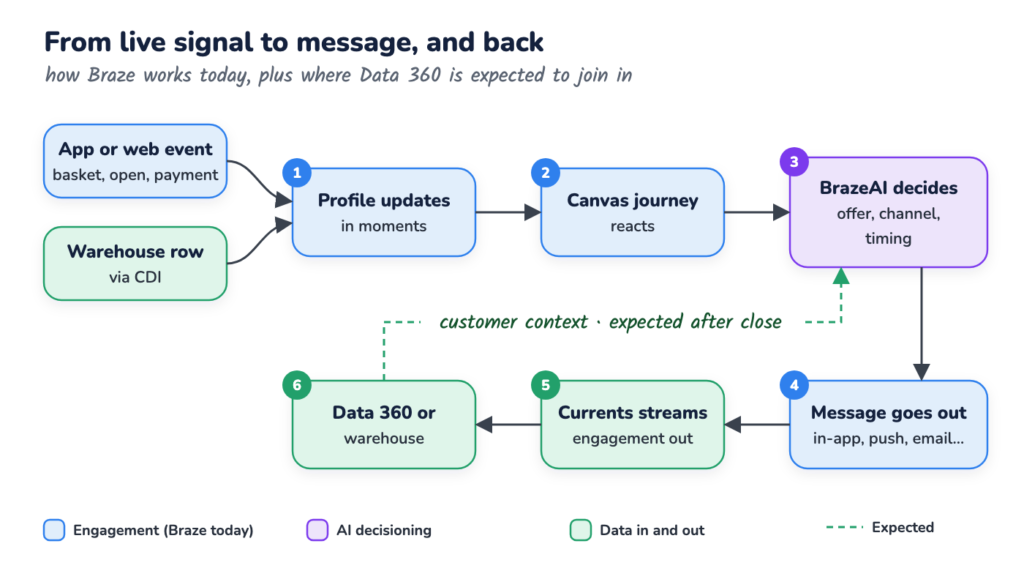
    What it is: Braze takes live signals from apps, websites and back-end systems, updates the profile continuously, and lets a Canvas react while the customer is still in the session.

    Today in Salesforce: most of us build engagement around data extensions, scheduled automations and journey entry events. It works, but “real time” usually involves some engineering.

    What Braze adds: behaviour-led journeys as the default, not the exception. Salesforce says the event-streaming architecture turns “live customer signals and data from cloud data warehouses and other platforms” into messages and journeys.

    Where it’s expected to plug in: Data 360 for the customer context, Marketing Cloud for orchestration.

    Watch-out: Futurum’s Keith Kirkpatrick puts it bluntly: “Salesforce will now run two engagement engines”. Which one owns a given journey is still an open question.

    Braze Salesforce real-time loop: live signal into a Braze Canvas, BrazeAI decides, message sent, Currents streams results back to Data 360

    Example scenarios

    • A food delivery app sees a basket abandoned at checkout and nudges in-app within the same session, not the next morning.
    • A fitness brand notices a member hasn’t booked a class in 10 days and triggers a personalised push, with the email as fallback.

    2. Mobile and in-app depth

    If Braze has a reputation for anything, it’s this. And it’s the gap many of us feel most when a client’s app team joins the room.

    What it is: channels that live inside the product, not just the inbox. Braze’s channel documentation lists in-app messages, Content Cards, Banners, push, plus email, SMS/MMS/RCS, WhatsApp, LINE, KakaoTalk and webhooks.

    What Braze adds:

    • Content Cards — “a highly targeted, dynamic stream of rich content”, embedded in apps and websites.
    • Live Activities — iOS lock-screen updates (think delivery trackers), which Braze can start and update remotely via its Live Activities API.
    • In-app messages and Banners — shown in context while the customer is using the product.

    Where it’s expected to plug in: Salesforce says Braze’s “deep mobile and app capabilities, including in-app messages, personalized content feeds, and live updates” will work alongside email, web and messaging channels.

    Watch-out: these channels need the Braze SDK in the app. So the mobile team, not just the marketing team, becomes part of the conversation.

    Example scenarios

    • A retailer’s app shows a Content Card with a member-only offer that disappears the moment it’s redeemed in store.
    • A travel brand runs a Live Activity on the lock screen showing gate changes and boarding status.

    3. AI decisioning with BrazeAI

    Now this one is particularly interesting.

    What it is: AI that chooses what to send, where and when for each customer. Braze lists Intelligent Channel, Intelligent Timing, Item Recommendations, Operator, agents and Decisioning Studio under BrazeAI.

    What Braze adds: BrazeAI Decisioning Studio, which started life as OfferFit (acquired by Braze in 2025). Braze describes it as using reinforcement learning and contextual bandits to choose the message, channel, timing and incentive for each customer, continuously experimenting rather than relying on one-off A/B tests.

    Where it’s expected to plug in: Salesforce says that bringing Braze’s AI decisioning together with “Salesforce’s customer context and Agentforce” would connect marketing to commerce, sales and service.

    Watch-out: more automated decisions raise governance questions. Who approves the offer rules? Who owns the decision when the model picks something odd?

    Example scenarios

    • A subscription business lets the model choose between a discount, a free month or no offer at all for each at-risk customer.
    • A bank tests which of five onboarding nudges, on which channel, gets new customers to set up a direct debit.

    4. Composable data plumbing

    This one is quieter, but for architects it might be the most useful.

    What it is: Braze is built to work with data where it already lives. Its data ingestion guide describes two flavours:

    • Persistent — Cloud Data Ingestion (CDI) syncs warehouse tables onto Braze profiles, as often as every 5 minutes.
    • Zero-copy — CDI Segments and CDI Canvas triggers query the warehouse without writing to the profile.

    And on the way out, Currents is “a real-time data stream of your engagement events” to warehouses, analytics tools and CDPs.

    Where it’s expected to plug in: Data 360. According to the press release, Salesforce and Braze “share a commitment to an open, composable approach”, and Data 360 already leans heavily on zero-copy.

    Watch-out: I couldn’t find an official native Braze ↔ Data 360 connector today. Current Salesforce links are mostly webhooks, APIs and third-party connectors.

    Example scenarios

    • Loyalty tiers stay in Snowflake and trigger a Canvas directly, without copying every attribute into Braze.
    • Every send, open and click streams back via Currents so the service team sees the full message history.

    Where Braze fits in the Salesforce ecosystem

    Here’s the part of the Braze Salesforce announcement I found most telling.

    Salesforce doesn’t frame this as “Braze joins Marketing Cloud”. It says Braze is expected to complement all four layers of its architecture: Data 360, Customer 360, Agentforce and SIForce.

    Braze Salesforce fit: where Braze capabilities are expected to plug into Data 360, Customer 360, Agentforce and SIForce

    Kirkpatrick at Futurum summarises the split neatly: “Data 360 supplies the customer data; Braze supplies the decisioning and the channels that deliver the message.”

    The press release names SIForce but doesn’t explain it, so I’d wait for more detail before reading too much into that layer.

    Here’s how the four specialities line up in a combined Braze Salesforce stack:

    Braze specialityWhat it bringsExpected Salesforce fitOpen question
    Real-time streamingProfiles and journeys that react to live eventsData 360 + Marketing CloudWhich engine owns the journey?
    Mobile and in-appIn-app messages, Content Cards, Banners, Live ActivitiesMarketing Cloud (Customer 360)Does it replace or sit beside MobilePush?
    AI decisioningBrazeAI, Decisioning Studio (formerly OfferFit)AgentforceHow do agents and Decisioning Studio share decisions?
    Composable dataCDI in (persistent or zero-copy), Currents outData 360Native connector, or more plumbing?

    So what should we take away from the Braze Salesforce deal?

    A few questions I’d keep handy for the next client conversation.

    1. Which engine owns the journey?

    For now, both do. Until Salesforce publishes a roadmap, decide per use case, not per platform. MarTech’s Constantine von Hoffman makes the same point: teams need to know “which system owns journey orchestration”.

    2. Where does the profile live?

    Data 360, Braze, the warehouse, or all three? The answer drives identity, consent and reporting, and it’s worth writing down before anyone builds anything.

    3. Is the use case batch or behaviour-led?

    A monthly newsletter doesn’t need event streaming. A basket-abandon nudge inside the app does. Sorting use cases this way is useful whatever happens next.

    4. What changes before close?

    Nothing, officially. The acquisition is expected to close in FY2028 and needs approvals. Braze’s CEO says they’ll “continue building as Braze”. So existing contracts and roadmaps stand for now.

    The bigger picture

    The Braze Salesforce deal is less about adding another tool and more about adding a speed.

    Salesforce has the data layer, the CRM and the agents. What Braze brings is a mature, battle-tested way to act on behaviour in the moment, especially inside apps.

    Will it be smooth? Well… that’s still the open question. West Monroe’s Alex Torgerson told TechTarget: “The strategic logic is sound, but the value hinges entirely on integration…and customer migration.”

    So instead of asking:

    “Should we move to Braze?”

    I’d ask:

    “Which of our journeys actually need to react in seconds?”

    Because that’s the question the Braze Salesforce deal really puts on the table.

    And that’s exactly where the real-time edge earns its place.

    Want more on where Salesforce is taking marketing? Read my breakdown of smart features in the new Marketing Cloud Next.

  • Marketing Cloud Next consent: the hidden cube

    Marketing Cloud Next consent: the hidden cube

    “We’ve imported all the opt-ins. So why did nobody get the email?”

    If you’ve started a Marketing Cloud Next project, there’s a good chance you’ve heard that question already. Or asked it.

    Consent in Marketing Cloud Next looks straightforward on the surface. A subscription, an opt-in, a send.

    Cool, right?

    But here’s the thing worth paying attention to with Marketing Cloud Next consent: it doesn’t behave like the opt-out checkbox many of us grew up with in CRM, or the All Subscribers list in Marketing Cloud Engagement.

    It has more dimensions than that. It starts at “no”. And it only counts if it arrives the right way.

    Salesforce has a whole Trailhead module on consent management for Marketing Cloud Next, plus a detailed help article on the consent tools and concepts. And there are some interesting details buried in them.

    So, let’s have a look.

    Marketing Cloud Next consent in a nutshell

    If you only have 30 seconds:

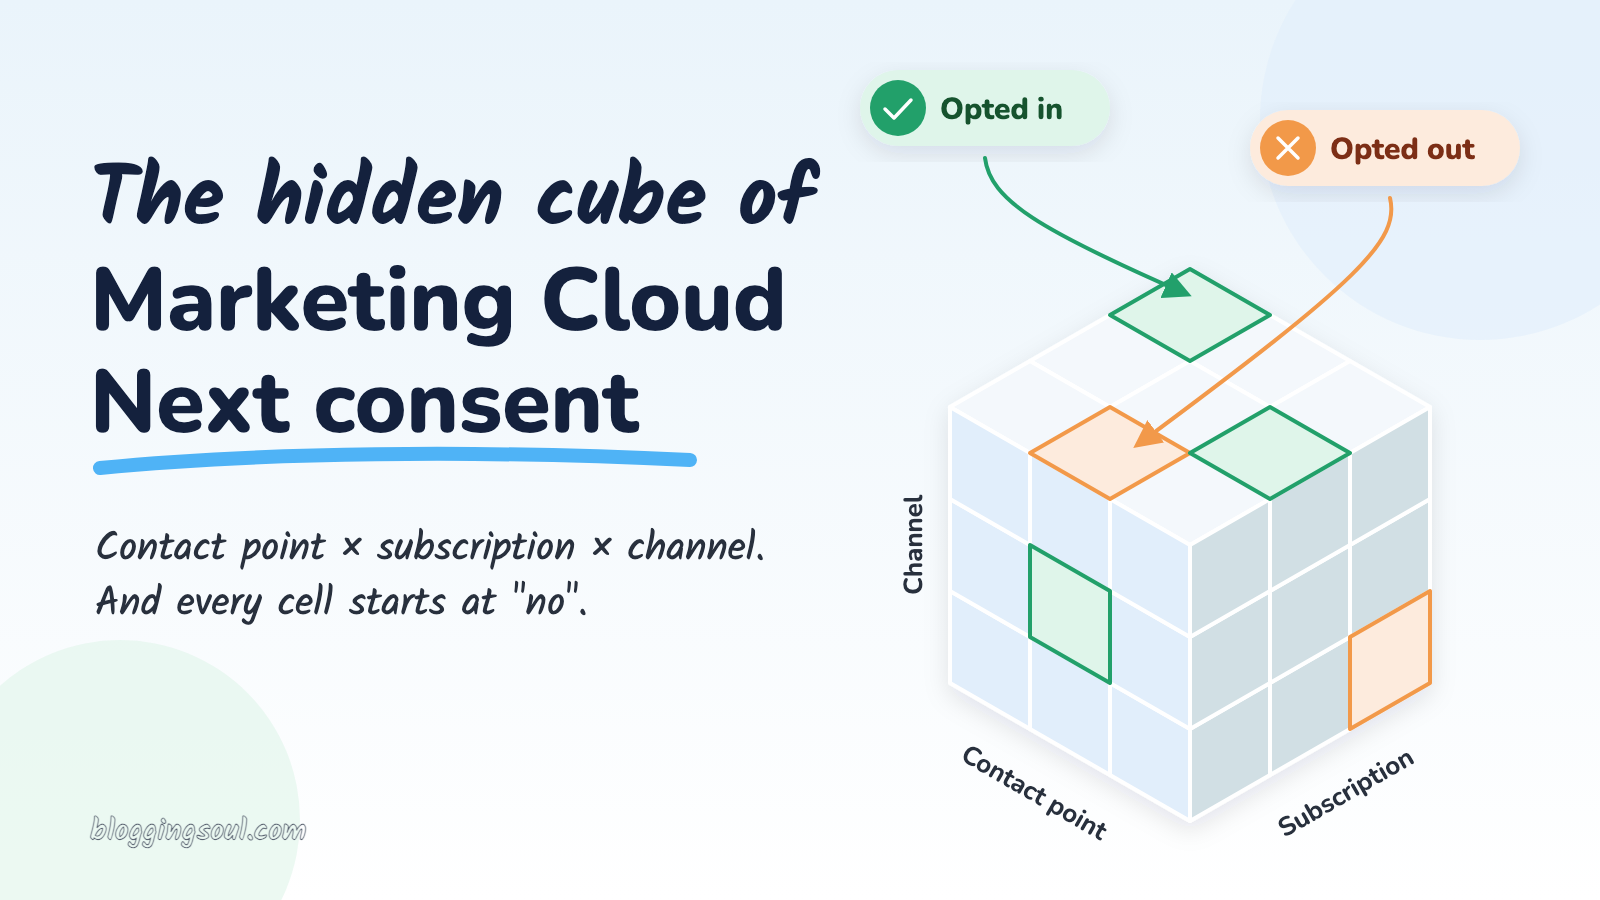
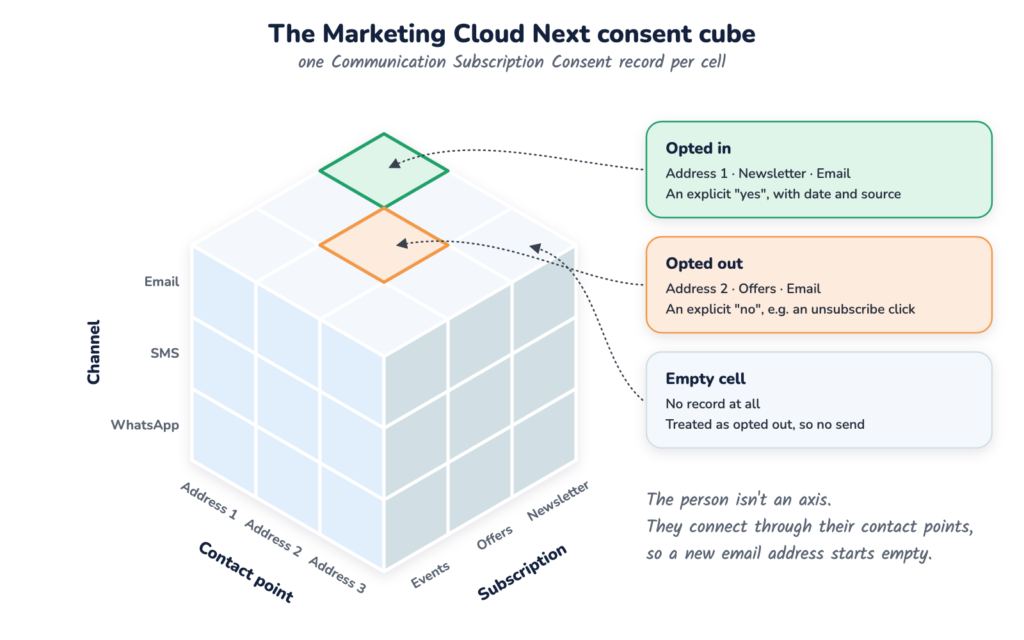
    • It’s a cube, not a checkbox: consent is stored per contact point (an email address or phone number), per subscription, per channel.
    • The default is “no”: no opt-in record means the message doesn’t go.
    • Channels have different rules: promotional email is checked, transactional email isn’t by default, and SMS, WhatsApp and RCS always are.
    • It lives in Data 360: and it has to be written through the consent service, not mapped straight into the data model.
    • Taking consent away has limits too: “unsubscribe from all” and SMS STOP are narrower than they sound.

    The rest of this post is the detail behind those five lines.

    First, what does Salesforce mean by consent here?

    Salesforce says that Marketing Cloud Next manages all consent centrally using Data 360, with preferences stored as data model objects (DMOs).

    The help documentation names four objects behind Marketing Cloud Next consent. Here’s what each one means in plain terms:

    • Communication Subscription: the topic someone can subscribe to, like “Newsletter” or “Product updates”. A default “Marketing” subscription is created for you.
    • Engagement Channel Type: the channel, such as email, SMS or WhatsApp.
    • Communication Subscription Channel Type: a subscription on a specific channel, for example “Newsletter by email”.
    • Communication Subscription Consent: the record that says whether a specific email address or phone number is opted in or out of that subscription on that channel, with the date and source.

    Trailhead describes that last one as the record that “defines the ultimate truth”.

    So that’s the one to keep your eye on.

    The Marketing Cloud Next consent cube

    The way I like to picture it is a 3-D table. A cube.

    My first instinct was to call the three axes Contact — Subscription — Contact Point. But the documentation gives us a slightly more precise picture than that.

    Salesforce says consent is “tied to the contact point value, as opposed to the Unified Individual record itself”.

    So the person isn’t really an axis. The three axes are:

    • Contact point: the actual email address or phone number.
    • Subscription: the topic, like Newsletter or Offers.
    • Channel: email, SMS, WhatsApp or RCS.

    Each cell in the cube is one Communication Subscription Consent: opted in, opted out, or (most of the time) empty.

    The person sits outside the cube. They connect to it through their contact points.

    The Marketing Cloud Next consent cube with axes for contact point, subscription and channel, showing one opted-in cell
    Three axes, one cell per decision: contact point × subscription × channel

    Salesforce’s partner workshop on consent describes four levels of consent, from the whole individual (Level 1) down to “a specific contact point value and a specific subscription type” (Level 4). Marketing Cloud Next supports Level 4, the most granular one.

    That’s a pretty big shift.

    Example scenarios

    • Priya opts in to the Newsletter with her work email. Her personal email stays an empty cell, even though it’s the same person.
    • A retailer’s “Offers” subscription runs on email and SMS. A customer opts in to email offers, and that says nothing about SMS offers.

    No record, no send

    Now this one is particularly interesting if you’re coming from Marketing Cloud Engagement.

    Marketing Cloud Next consent uses strict opt-in. According to Trailhead, if there’s no record, “the system assumes they have opted out”.

    Not “unknown”. Not “probably fine”. Opted out.

    As the module puts it, “the sheer absence of a recorded ‘Yes’ is enough” to stop the message.

    So most of the cube is empty, and empty means no.

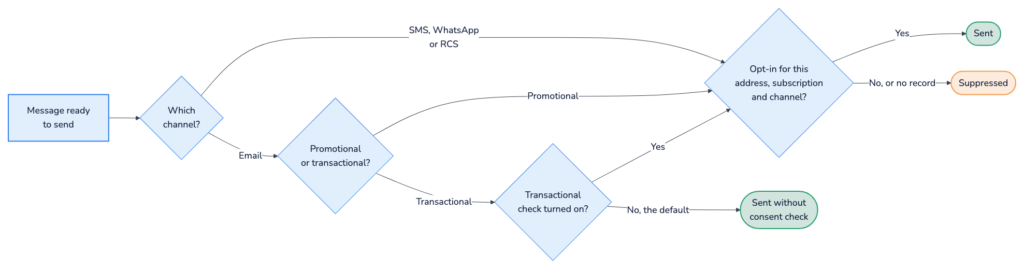
    How strictly that applies depends on the channel and the type of message. The help article explains that the consent check requires you to pick a communication subscription when you send, and makes sure each recipient is opted in.

    • Promotional email: consent required.
    • Transactional email: consent checks are disabled by default. Admins can change the settings in Setup.
    • SMS, WhatsApp and RCS: consent required for any type of message.

    And here’s the interesting part: for SMS, the partner workshop says the product “does not provide a mechanism to bypass SMS consent enforcement”. Even a delivery update needs an opt-in.

    Marketing Cloud Next consent check at send time: channel, message type and opt-in record decide whether a message is sent
    What the consent check asks before a message goes out

    Example scenarios

    • 40,000 CRM contacts are migrated without consent records. The first newsletter goes to almost nobody, because every cell is empty.
    • An order-shipped SMS fails for customers who only ever opted in to email. SMS has no transactional exemption.

    Marketing Cloud Next consent by channel

    Here’s the same thing as a table, because it’s a lot easier to scan:

    MessageConsent checkDefaultOpt-in record needed for
    Promotional emailYesOnThat email address + subscription + email channel
    Transactional emailOptionalOff (can be turned on in Setup)Only if the check is turned on
    SMS (any type)YesOn, no bypassThat phone number + subscription + SMS channel
    WhatsApp / RCS (any type)YesOnThat phone number + subscription + that channel

    One nuance on transactional email: Trailhead says transactional emails don’t need a promotional subscription, but you should still respect global opt-outs. The workshop notes transactional email “may rely on a legitimate interest basis” under frameworks like GDPR.

    That’s a legal call, not a technical one. Worth checking with whoever owns privacy on your project.

    Consent has to travel through Data 360

    This is the part that catches most teams out.

    Marketing Cloud Next consent lives in Data 360. So far, so expected.

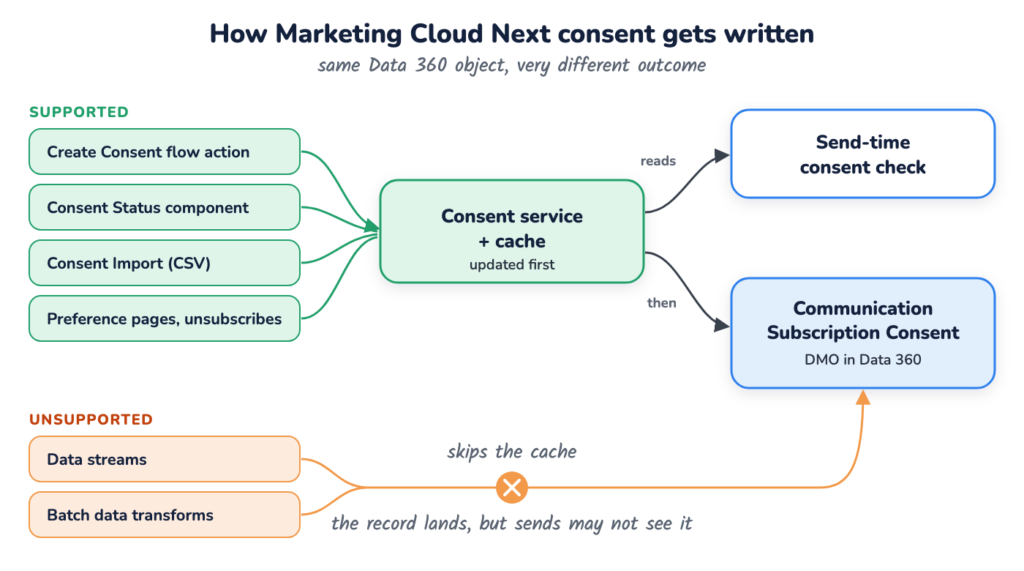
    But it’s not enough for the data to land in Data 360. It has to get there through the consent service.

    “Consent is just data in Data 360, so we can load it with a data stream.”

    Well… yes. But the documentation gives us more detail than that.

    According to the partner workshop, sends read from an internal consent service and cache layer. That’s how “consent changes are immediately respected at send time”. The Create Consent action, for example, updates that cache first, then writes the record into Data 360.

    Data streams and batch data transforms can write to the Communication Subscription Consent DMO. But they don’t update the cache, so the send may never see the change.

    Trailhead says it plainly: “Updating the data model object (DMO) directly does not update the consent for Marketing as expected.”

    So, which routes are supported? Salesforce’s troubleshooting article lists them:

    • Create Consent flow action: for forms, events and automation. It’s included by default in Signup Form campaign flows.
    • Consent Status component: for updating one record by hand on the contact page.
    • Consent Import: a CSV upload of up to 50,000 rows.
    • More than 50,000 rows: stage the data in a custom DMO, then run a Data 360-triggered flow that calls Create Consent.

    Preference pages and unsubscribe links are the built-in way for subscribers to change consent themselves.

    Anything else, the article calls “an unsupported write path”.

    Supported and unsupported ways to write Marketing Cloud Next consent: through the consent service and cache, or straight into the DMO
    Same Data 360 object, two very different outcomes
    • Older flow actions: Salesforce says not to use the MessagingConsent and MessagingConsentV2 flow actions. Create Consent replaces them.
    • Delay: expect around 15 minutes before an update shows up in Data 360, according to the troubleshooting article. The send check itself reads the cache.
    • Audit: a consent audit trail records every change, while the consent record itself only holds the current status.

    Example scenarios

    • Consent from a legacy ESP is mapped into the consent DMO with a data stream. It looks perfect in Data Explorer, but the sends don’t pick it up.
    • A CRM opt-in field changes on a Contact. A record-triggered flow calls Create Consent so the change actually reaches Marketing Cloud Next.

    Taking consent away

    Taking Marketing Cloud Next consent away has its own nuances, and they’re worth knowing before a customer complaint teaches you.

    • Unsubscribe links: every promotional email needs one, or a link to the preference page. A click sets the consent record to opted out.
    • “Unsubscribe from all”: on the standard preference page, this removes the contact point from all existing subscriptions. Trailhead says it does not persist as a permanent block, so a subscription you create next month isn’t covered. (Though with default opt-out, nobody is opted in to it yet either.)
    • SMS STOP: STOP, CANCEL and UNSUBSCRIBE are recognised, but STOP only opts out of that specific sender number, not all SMS from the brand.
    • Deleting subscriptions: don’t. Salesforce warns that deleting a Communication Subscription permanently deletes all related consent history. Hide it from the preference pages instead.

    Nobody wants to be the admin who tidied up an old subscription and took two years of consent history with it.

    Example scenarios

    • A customer texts STOP to your marketing short code, then still gets texts from your service number. Each sender number is opted out separately.
    • A “Spring Sale 2025” subscription is no longer needed. Hide it from the preference page rather than deleting it.

    So what should we actually take away from all this?

    For me, the biggest takeaway is this:

    “This contact is opted in” isn’t really a complete statement in Marketing Cloud Next.

    Which address? For which subscription? On which channel?

    When I’m working on Marketing Cloud Next consent, I’d ask four questions.

    1. Which cell of the cube are we talking about?

    Pin down the contact point, subscription and channel. If one of the three is missing, the answer is probably “not opted in”.

    2. Does this message actually need consent?

    Promotional email and anything on SMS, WhatsApp or RCS: yes. Transactional email: only if the check is turned on, and that’s a decision for your privacy team.

    3. How is consent getting in?

    Forms, imports, CRM sync, migrations. Every route should end in Create Consent, Consent Import or the Consent Status component, never a data stream straight into the DMO.

    4. What happens when things change?

    New email addresses, new subscriptions, STOP replies, retired topics. Each one has a rule, and none of them carry consent over for you.

    The bigger picture

    I really like where Salesforce has gone with Marketing Cloud Next consent.

    Strict opt-in, per channel, per address, with an audit trail. That’s a privacy-first design, and it’s an essential foundation if you’re sending across email, SMS and WhatsApp at the same time.

    But it does mean we need to change the question.

    Instead of asking:

    “Is this contact opted in?”

    I’d ask:

    “Is this email address or phone number opted in to this subscription, on this channel, and did that consent arrive through the consent service?”

    That’s a much more useful conversation, especially early in a project, before the first send suppresses your whole audience.

    Because, as we’ve seen, Marketing Cloud Next consent isn’t a checkbox. It’s a cube, it starts empty, and only the right tools can fill it in.

    So the next time someone says, “But they’re opted in!”, you know what to ask:

    “Well… opted in where?”

    Curious how the AI side of the platform works? Read Smart features in the new Marketing Cloud Next.

  • Data Cloud zero copy: the hidden trade-offs explained

    Data Cloud zero copy: the hidden trade-offs explained

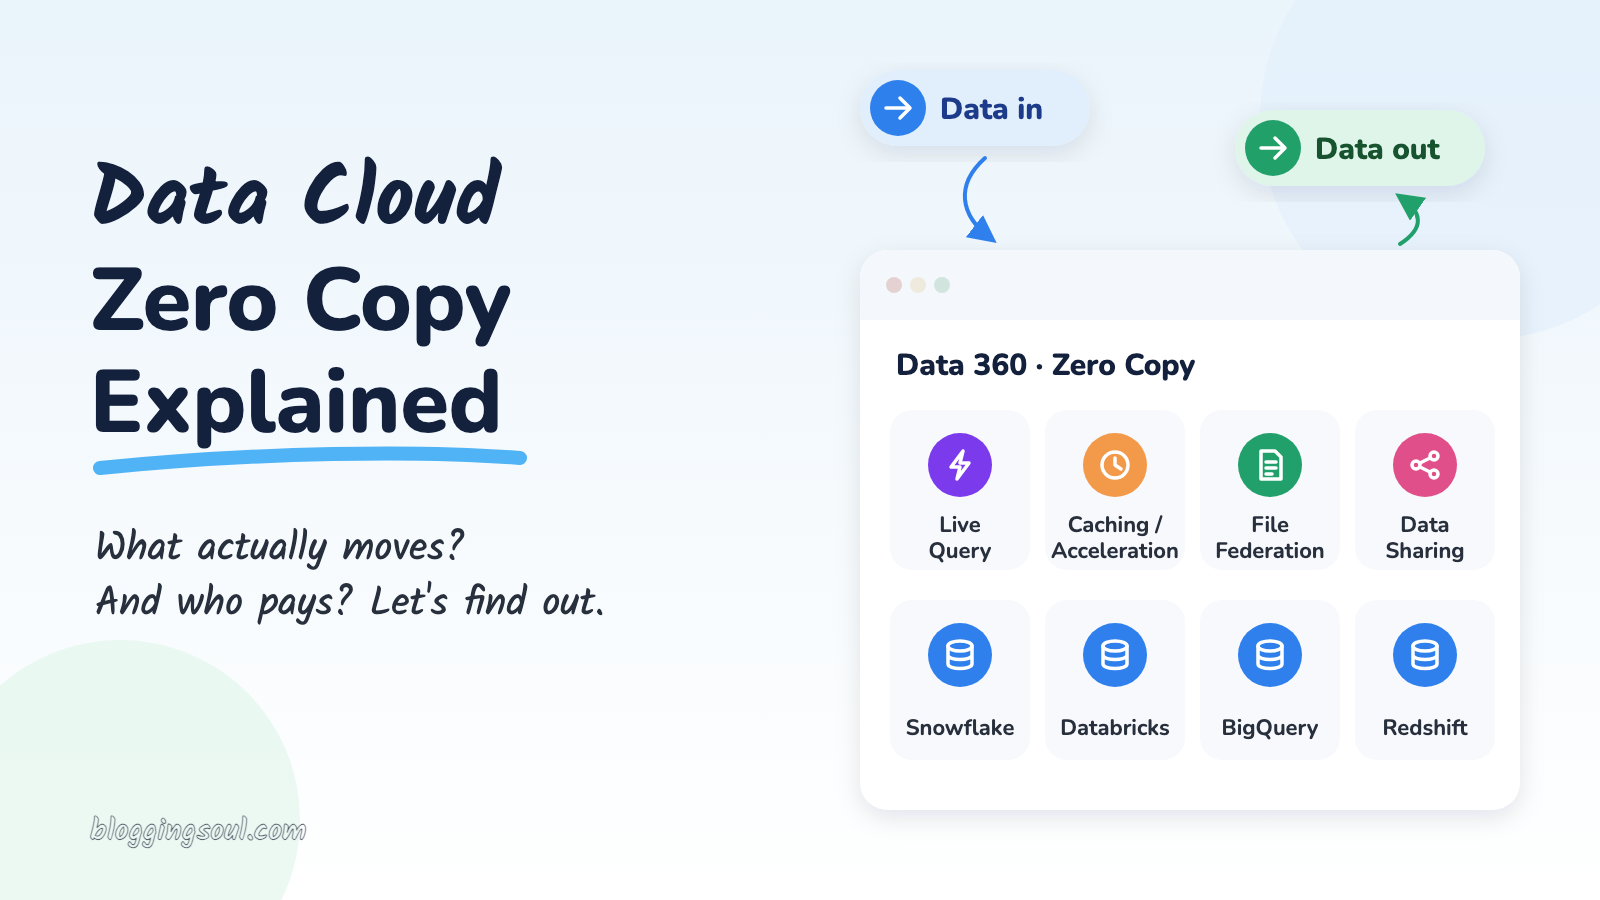
    Zero copy is one of those Data Cloud features that sounds almost too good to be true.

    Use the data sitting in Snowflake, Databricks, BigQuery or Redshift inside Salesforce… without copying it in.

    Cool, right?

    Quick naming note before we start: Salesforce renamed Data Cloud to Data 360 at Dreamforce 2025. Same platform, new name — so you’ll see both in this post, and in the documentation.

    But here’s the thing I think is worth paying attention to with Data Cloud zero copy: it isn’t one single feature.

    There are actually four different ways it can work.

    Some never store your data in Data 360. One of them does.

    Some run on your warehouse’s compute. Some don’t.

    And the cost — in Data 360 credits and on your warehouse bill — changes quite a bit depending on which one you pick.

    So, let’s have a look.

    Data Cloud zero copy in a nutshell

    If you only have 30 seconds:

    • Live query — Data 360 asks your warehouse; only the results come back.
    • Caching (acceleration) — a scheduled copy of the federated data, kept in Data 360.
    • File federation — Data 360 reads open-format files (Apache Iceberg) straight from your object storage.
    • Zero copy data sharing — the reverse direction: Data 360 data made available inside Snowflake, Databricks and co.

    The rest of this post is the detail behind those four lines.

    First, what does Salesforce mean by zero copy?

    Salesforce describes zero copy as a technology that “enables enterprises to access and query data without copying it”.

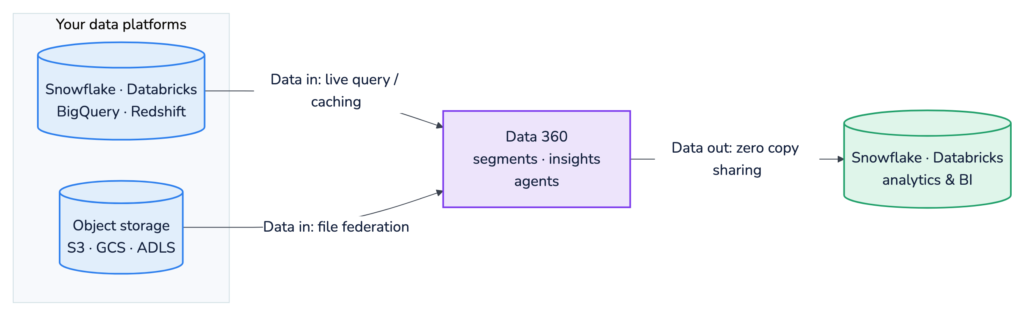
    It works in two directions:

    • Data in (zero copy data federation) — Data 360 uses data that lives in your lakehouse or warehouse, for things like segmentation and identity resolution, without ingesting it.
    • Data out (zero copy data sharing) — Data 360 data, such as unified profiles and calculated insights, is made available to an external platform without building an export pipeline.

    Out of the box, Salesforce lists Snowflake, Databricks, Amazon Redshift and Google BigQuery. The Zero Copy Partner Network launched in April 2024 with AWS, Databricks, Google Cloud and Snowflake, and Microsoft and IBM have joined since.

    Zero copy works both ways: federation in, sharing out
    Zero copy works both ways: federation in, sharing out

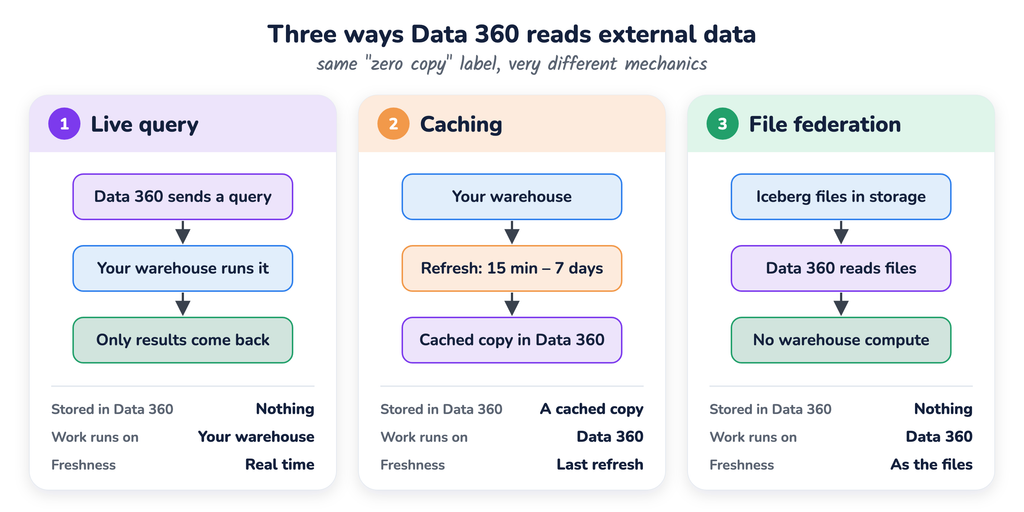
    The “data in” side is where it gets interesting, because Data 360 has three different ways to read that external data.

    Three ways in and where the work actually happens
    Three ways in and where the work actually happens

    Let’s get into it.

    1. Live query (query federation)

    This is the one most people picture when they hear “zero copy”.

    When Data 360 needs the data, it sends a query to the external platform. According to Salesforce’s Data 360 Interoperability guide, the query is pushed down to the source, the warehouse does the work, and only the results come back.

    Nothing is stored in Data 360.

    • Where the work runs: your warehouse
    • Freshness: as fresh as the source
    • Cost: Data 360 credits for each query and compute on your warehouse

    Example scenarios

    • A segment filters on loyalty tiers stored in Snowflake — checked when the segment publishes, not loaded overnight.
    • Order history in Redshift that’s only used now and then for an audience, so a full ingestion pipeline isn’t worth it.

    And here’s the bit to watch.

    Salesforce calls this a “pay-per-query model”, and warns that costs “may spike significantly at high QPS”. Performance also depends on the external system — overly broad queries and joins between Data 360 data and federated data are common causes of latency, according to this Salesforce blog.

    So “zero copy” doesn’t mean “zero cost”. It means the cost moves to query time.

    2. Caching (accelerated query)

    Now things get a little more interesting.

    Acceleration — you’ll also see it called caching or Accelerated Query — “temporarily stores cached copies of federated data in Data 360”.

    Yes… the zero copy option that involves a copy.

    The cache refreshes on a schedule you configure, anywhere from 15 minutes to 7 days. Queries then hit the cache instead of your warehouse, which makes them faster.

    • Where the work runs: Data 360 (your warehouse only works during refreshes)
    • Freshness: as of the last refresh
    • Cost: Data 360 credits for the rows cached, plus external storage costs

    One detail that’s easy to miss. Salesforce notes that “incremental refresh supports upserts only. Deleted records aren’t removed from the cache.” So a periodic full refresh is a good idea, otherwise deleted records can quietly hang around in your segments.

    Salesforce also says caching is “not suitable for sub-second decisioning”.

    Example scenarios

    • A daily dashboard built on a million records and viewed 20 times a day — read a lot, changes a little.
    • A product catalogue that changes weekly but is used in almost every segment.

    3. File federation

    The third option is the one the Salesforce blog calls “the third and best way” to connect to data lakes.

    Instead of asking your warehouse’s engine to run a query, Data 360 reads the data files directly from object storage — Amazon S3, Google Cloud Storage or Azure Data Lake Storage — using open table formats like Apache Iceberg. It’s read-only.

    Your warehouse’s compute isn’t involved at all.

    • Where the work runs: Data 360, reading the files directly
    • Freshness: whatever is in the files — Salesforce says it’s “not suitable for real-time dashboarding”
    • Cost: no cost on the external lake, and very little in Data 360 if you stay in the same region

    And region really matters here.

    The blog says that if your data lake and Data 360 are in the same region, “the cost is almost zero on both sides”. The architects’ guide goes further: for same-region setups, “credits aren’t consumed for the rows that are accessed”, while cross-region or cross-cloud access does consume credits.

    Performance depends on file format, partitioning and network I/O, so a well-organised lake matters.

    A note on availability: Salesforce’s zero copy page still labels file federation as beta, while Databricks’ documentationlists it as generally available. Check the current status for your platform before you design around it.

    Example scenarios

    • Years of transaction history in Iceberg tables on S3 — far too big to ingest, but useful for segments.
    • Propensity scores written to the lakehouse by the data science team, read by Data 360 in the same region.

    4. Zero copy data sharing

    And finally, the other direction.

    Data sharing makes Data 360 data available in an external platform, without an export job. The setup, as described in Snowflake’s documentation, has two parts:

    • A data share — which Data 360 objects you want to make available.
    • A data share target — the receiving account, such as your Snowflake account.

    Link the two, and the shared objects appear on the other side. In Snowflake, they show up as a data product you can mount.

    One limitation worth knowing: you can’t share an external data lake object, or a data model object mapped to one. In other words, you can’t federate data in and then share it straight back out.

    Example scenarios

    • Unified profiles and a lifetime-value calculated insight shared to Snowflake for the finance team’s BI reports.
    • The data science team trains a churn model in Databricks on shared Data 360 engagement data — and the scores come back in through federation.

    Data Cloud zero copy options side by side

    Here’s how the three “data in” options compare:

     Live queryCachingFile federation
    Stored in Data 360?NoYes, a cached copyNo
    Where the work runsYour warehouseData 360Data 360, reading files
    FreshnessReal timeLast refresh (15 min — 7 days)As current as the files
    Data 360 credits (quoted)70 per million rows retrieved2,000 per million rows cachedSame as live query; ~0 in the same region
    Cost on your sideWarehouse compute per queryExternal storageNone on the lake
    Best forFresh data, occasional useRead often, changes rarelyLarge lake data, same region

    The credit figures are the ones quoted in Salesforce’s Four lessons from implementing zero copy blog. Treat them as indicative, and check the credit consumption help article and your own contract before you build a business case.

    So what does it actually cost?

    The biggest surprise for most teams is that Data Cloud zero copy can cost money in two places: Data 360 credits, and your warehouse bill.

    Salesforce’s architects’ guide has two examples that show why the “right” option depends on how the data is used:

    • Caching wins: a dashboard on 1M records, with ~10K changes a day, viewed 20 times a day – about 600 credits a month with acceleration vs ~4,200 with live queries.
    • Live query wins: a segment published 20 times a day, on data that changes every 30 minutes – about 4,200 credits a month with live queries vs ~28,800 with acceleration.

    Same platform. Very different answers.

    The rule of thumb from the guide: if data is “accessed frequently but changes infrequently”, acceleration is typically more cost-effective.

    So what should we actually take away from all this?

    For me, the biggest takeaway is this:

    “We’re using zero copy” isn’t really a useful statement.

    Which zero copy? For which data? Read how often?

    When you’re designing a Data Cloud zero copy setup, I’d ask five questions.

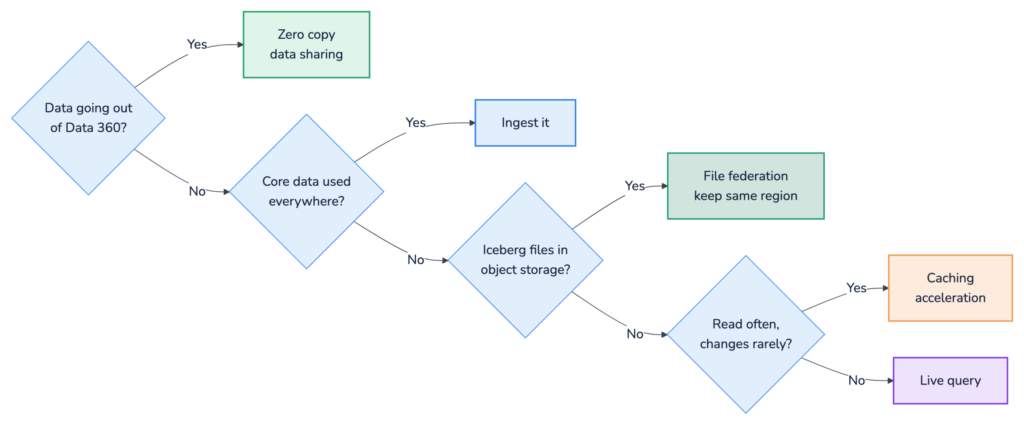
    Which zero copy option fits? A quick decision flow
    Which zero copy option fits? A quick decision flow

    1. Which way is the data going?

    Into Data 360? That’s federation. Out to Snowflake or Databricks? That’s sharing.

    2. Is this core data, or everything else?

    Salesforce’s guidance is to ingest critical data for canonical data models and core governance, and use zero copy for everything else.

    3. How fresh does it need to be?

    Minutes matter → live query. Yesterday’s data is fine → caching or file federation.

    4. How often will it be read?

    Read constantly but rarely changing → caching. Changing constantly → live query.

    5. Where does it live, and who governs it?

    Same-region object storage makes file federation very attractive. Avoid cross-region access unless you really need it.

    And remember that with federation, a lot of the security lives in the source. Salesforce recommends row-level security and masking policies directly in the federated systems. As the blog puts it: “Permissions and governance are not details; they form the backbone of the entire model.”

    The bigger picture

    I think Data 360 zero copy is one of the most useful things about the platform.

    And honestly, the fact that there are four options is a good thing.

    But we need to be a bit more precise in how we talk about it.

    Instead of asking:

    Should we use zero copy?”

    I’d ask:

    Which way is the data going, how fresh does it need to be, how often will we read it, and where does it live?”

    That’s a much more useful conversation.

    Because, as we’ve seen, Data Cloud zero copy doesn’t mean zero movement — and it definitely doesn’t mean zero cost.

    It means choosing where the work happens, and who pays for it.

    So the next time someone says, “Let’s just use zero copy”, you know what to ask:

    “Well… which zero copy are we talking about?”

    If you’re curious how Data 360 data feeds the new AI features in Marketing Cloud, check out my recent post on smart features in the new Marketing Cloud Next.


  • Smart features in the new Marketing Cloud Next

    Smart features in the new Marketing Cloud Next

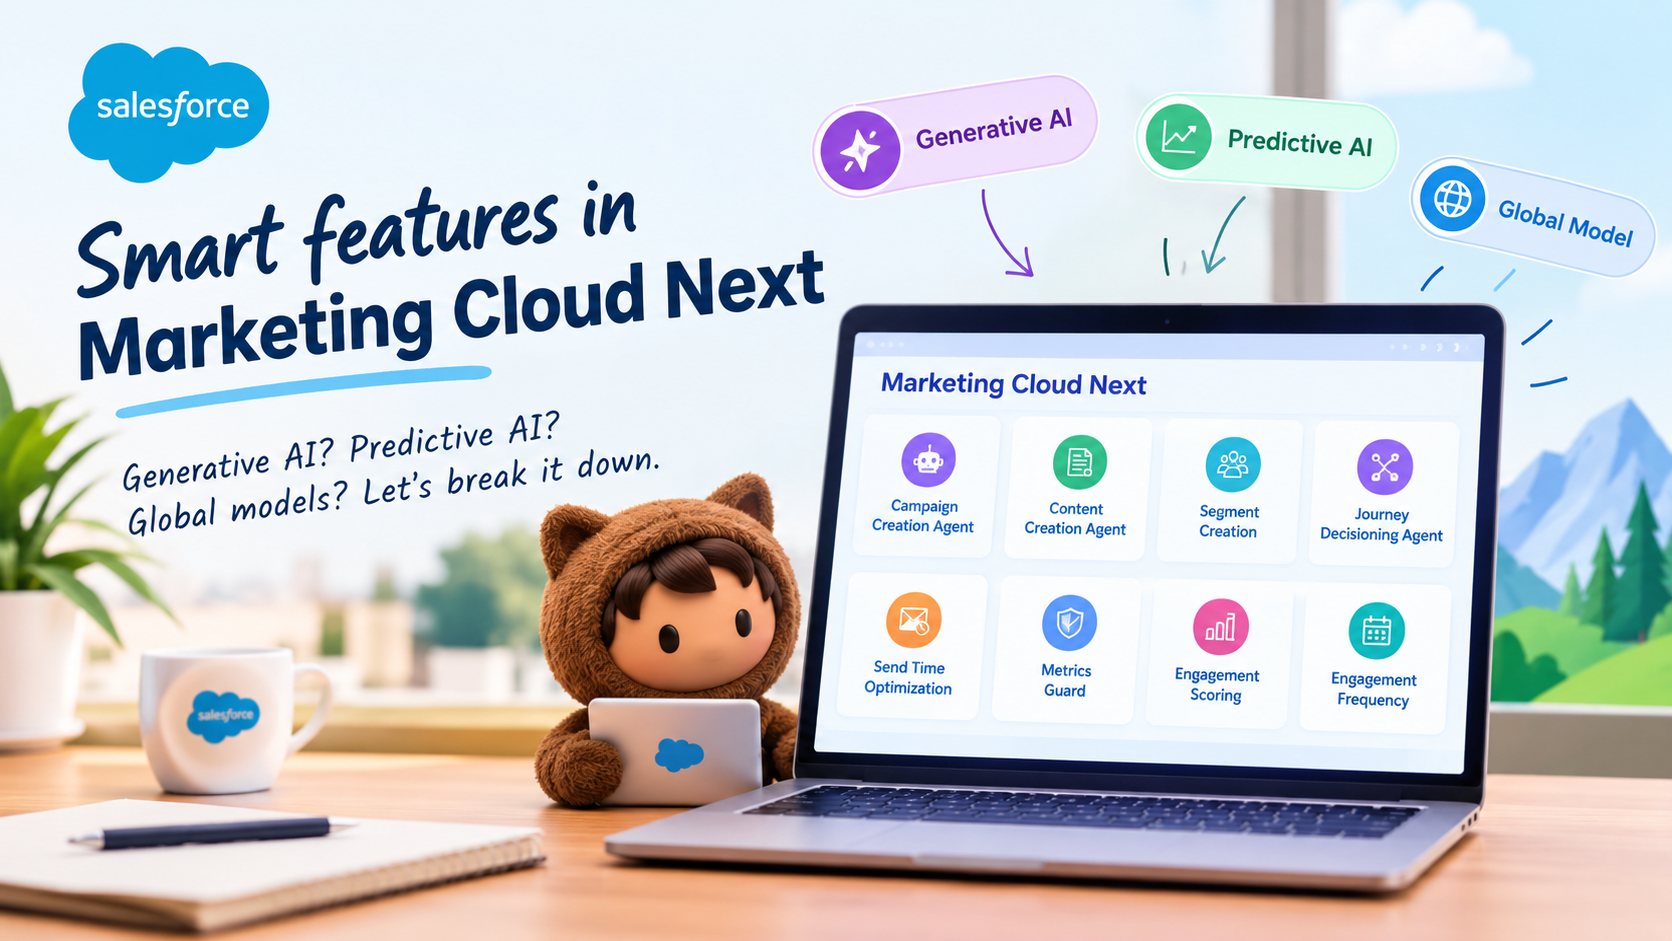
    AI is becoming a pretty big part of Marketing Cloud Next. And if you’ve been following the Salesforce ecosystem lately, you’ll know that we now have everything from Agentforce agents creating campaigns to Einstein features deciding when and how often we should communicate with customers.

    Cool, right?

    But there’s something I think is worth paying a bit more attention to when we talk about these features: what actually happens to the data behind the scenes?

    Salesforce has published some useful information about AI data usage in Marketing Cloud Next, including which customer data each feature uses, whether it uses a generative AI model, and whether it uses what Salesforce calls a global model.

    And there are some interesting differences between the features.

    So, let’s have a look.

    First, what does Salesforce mean by AI data usage?

    Before jumping into individual features, there are two types of data Salesforce calls out:

    • Customer Data — data submitted by the customer to Salesforce services.
    • Usage Data — data relating to users’ interactions with Salesforce.

    Salesforce also makes an important statement in the documentation:

    Data submitted to an AI feature can be used to train AI models, improve Salesforce services and features, or develop new features that customers can access without additional cost.

    That sentence is definitely worth knowing if you’re involved in Salesforce architecture, security, governance or client conversations around AI.

    But here’s where it gets interesting.

    Not every AI feature works in the same way.

    Some use generative AI. Some don’t.

    Some use a global model. Some don’t.

    And the actual customer data being used varies quite a bit from feature to feature.

    Let’s get into it.


    Agentforce – Campaign Creation Agent

    If you’ve spent any time looking at Agentforce in Marketing Cloud Next, this is probably one of the features that immediately catches your attention.

    The Campaign Creation Agent is designed to help with the campaign creation process. Rather than starting with a completely blank canvas, the agent can work with information already sitting in your Marketing Cloud environment.

    Salesforce identifies the following data as being used:

    • Campaigns
    • Briefs
    • Engagement Data from Data Cloud
    • CMS Assets
    • Flows

    And here’s the first interesting bit.

    The Campaign Creation Agent uses a generative AI model, but Salesforce identifies it as not using a global model.

    So when we hear “generative AI”, we shouldn’t automatically jump to the conclusion that our customer data is being sent into some single global model.

    There’s a distinction here.

    Generative AI model: Yes

    Global model: No

    That’s a pretty useful distinction to understand when you’re having those inevitable AI governance conversations with customers.


    Agentforce – Content Creation Agent

    Now we get to something that is probably going to feel very familiar to Marketing Cloud users: creating content.

    The Content Creation Agent is designed to help marketers create campaign content using information that’s already available to them.

    Salesforce identifies these as the data sources used:

    • Campaigns
    • Briefs
    • CMS Assets

    And, just like the Campaign Creation Agent, it uses a generative AI model.

    But again, Salesforce identifies no global model usage.

    This is one of those areas where I think it’s worth being precise with the language.

    It’s easy to say:

    “Salesforce is using our marketing content to train AI.”

    But the actual documentation gives us more detail than that.

    The feature uses customer data as part of its AI functionality, and Salesforce says data submitted to AI features can be used to train models or improve services. However, Salesforce specifically identifies this feature as not using a global model.

    That’s an important distinction.


    Segment Creation

    Now this one is particularly interesting if you’re working with Data Cloud.

    Segment Creation uses segments in Data 360 as the customer data involved in the feature.

    The idea here is pretty cool: AI can help marketers work with audience segmentation rather than requiring them to manually construct every piece of logic themselves.

    And, once again, Salesforce identifies it as:

    Generative AI: Yes

    Global model: No

    So we’ve now got three AI capabilities where generative AI is being used, but Salesforce doesn’t identify a global model:

    • Campaign Creation Agent
    • Content Creation Agent
    • Segment Creation

    This is a useful pattern to keep in mind.


    Einstein Send Time Optimization

    Now things get a little more interesting.

    If you’ve worked with Marketing Cloud for a while, Einstein Send Time Optimization probably doesn’t need much introduction.

    The idea is fairly straightforward: rather than sending an email at the same time to everyone, the system looks at engagement behaviour and determines when an individual is more likely to engage.

    The data Salesforce identifies includes:

    • Sends
    • Clicks
    • Opens
    • Unsubscribes
    • Spam complaints
    • Associated timestamps
    • Data and metadata about customer sending patterns
    • Information about how campaigns are executed

    But here’s the important part:

    Send Time Optimization does not use a generative AI model.

    Instead, Salesforce identifies it as using a global model.

    And in Growth Edition, Salesforce says this global-model usage is required.

    Wow — that’s quite different from the Agentforce examples we’ve just looked at.

    This is a good reminder that “AI” doesn’t automatically mean generative AI.

    There are plenty of predictive AI capabilities in Marketing Cloud that have been around well before the current generative AI boom.


    Einstein Metrics Guard

    Metrics Guard is another interesting one.

    If you’ve ever looked at Marketing Cloud engagement numbers and thought, “Hmm… are all these opens and clicks actually real?”, this is where Metrics Guard comes in.

    Email security systems and automated scanners can sometimes generate opens and clicks that don’t represent genuine human engagement.

    Metrics Guard is designed to help identify and account for that kind of activity.

    Salesforce identifies the following data as being used:

    • Email sends
    • Opens
    • Clicks
    • Unsubscribes
    • Bounces
    • Spam complaints
    • Data and metadata about customer sending patterns

    And here’s the important distinction:

    Generative AI model: No

    Global model: Yes

    Salesforce marks the global model usage as required.

    So, again, this isn’t about an AI assistant writing your next email campaign.

    It’s a predictive AI capability working with email engagement data.


    Agentforce – Journey Decisioning Agent

    Now let’s jump back into Agentforce territory.

    The Journey Decisioning Agent is aimed at the customer journey side of things. Instead of AI simply helping us write content, we’re starting to see AI involved in decisions around customer journeys.

    Salesforce identifies:

    • Journeys
    • Subscriber content

    as the customer data used.

    And, like the other Agentforce features we’ve looked at:

    Generative AI model: Yes

    Global model: No

    This is where things start getting really interesting for Marketing Cloud practitioners.

    We’re moving from AI helping with individual tasks to AI becoming part of the actual decision-making and orchestration experience.

    That’s a pretty big shift.


    Einstein Engagement Scoring

    Engagement Scoring is another feature that takes a more predictive approach.

    Rather than generating content, it’s looking at engagement behaviour and trying to understand how likely a contact is to engage.

    The data involved includes things such as:

    • Email sends
    • Opens
    • Clicks
    • Unsubscribes
    • Bounces
    • Spam complaints
    • Data and metadata about customer sending patterns

    And here’s the interesting part:

    Generative AI model: No

    Global model: No

    So despite being an Einstein AI feature, there’s no generative AI and no global model identified for this feature.

    This is a great example of why we shouldn’t lump every Einstein feature into the same bucket.


    Einstein Engagement Frequency

    And finally, we have Einstein Engagement Frequency.

    The name probably gives away what this one is about.

    The feature looks at engagement behaviour to help determine how frequently an individual contact should receive communications.

    Nobody wants to be that brand that sends five emails in two days and then wonders why engagement has dropped!

    The data involved includes:

    • Email sends
    • Opens
    • Clicks
    • Unsubscribes
    • Bounces
    • Spam complaints
    • Data and metadata about customer sending patterns

    Salesforce identifies:

    Generative AI model: No

    Global model: No

    So, once again, we’re looking at predictive AI rather than generative AI.


    So what should we actually take away from all this?

    For me, the biggest takeaway is this:

    “Marketing Cloud Next uses AI” isn’t really a useful statement anymore.

    It’s a bit like saying “Salesforce uses data”.

    Well… yes. But what data? Where? For what purpose?

    The same thinking applies to AI.

    When you’re looking at a particular Marketing Cloud Next feature, I’d ask four questions:

    1. What data does the feature use?

    Is it campaign information?

    Subscriber content?

    Data 360 segments?

    Email engagement?

    CMS assets?

    The answer is different for each feature.

    2. Is it generative AI or predictive AI?

    This is a really important distinction.

    Agentforce features such as Campaign Creation Agent and Content Creation Agent use generative AI.

    Features such as Send Time Optimization and Engagement Scoring are predictive.

    They’re doing very different jobs.

    3. Does Salesforce identify it as using a global model?

    This is probably the question I’d pay the most attention to when discussing data governance.

    And the answer varies.

    For example:

    Send Time Optimization and Metrics Guard → Global model: Yes

    Whereas:

    Campaign Creation Agent, Content Creation Agent, Segment Creation, Journey Decisioning Agent, Engagement Scoring and Engagement Frequency → Global model: No

    4. Is the global model usage required?

    This is another important detail.

    For Send Time Optimization, Salesforce identifies global-model usage as required in Growth Edition.

    For Metrics Guard, it’s marked as required.

    That’s very different from simply having an optional AI feature switched on somewhere in your org.


    The bigger picture

    I think we’re going to have more and more of these conversations as Salesforce continues bringing AI into Marketing Cloud.

    And honestly, that’s a good thing.

    But we need to get a little more precise in how we talk about it.

    Instead of asking:

    “Does Marketing Cloud use our data for AI?”

    I’d ask:

    “Which Marketing Cloud feature are we talking about, what data does it use, what type of model does it use, and does Salesforce identify that model as global?”

    That’s a much more useful conversation.

    Because, as we’ve seen, the answer changes depending on the feature.

    And that’s probably the most interesting thing about Salesforce’s documentation here.

    AI isn’t one big bucket.

    Marketing Cloud Next has generative AI, predictive AI, customer-data-driven features and global-model-driven features — and they don’t all work in the same way.

    So the next time someone says, “But Salesforce AI uses our customer data, right?”, you can give them the much more useful answer:

    “Well… which AI feature are we talking about?”

    And that’s where things get interesting.


    Check out my recent post on different AI tools that could be helpful if you are into technology

  • Claude vs Cursor vs Cline vs Copilot: which AI coding agent suits you?

    Claude vs Cursor vs Cline vs Copilot: which AI coding agent suits you?

    A year ago, picking between AI coding assistants was simple. One did autocomplete. One did chat. One did “agents”, whatever that meant that week.

    Now? They all do a bit of everything.

    Claude Code has IDE extensions. Copilot has an agent mode. Cursor runs agents in the background. Cline plugs into whatever model you like.

    Cool, right? Well… yes. But it also makes the choice harder, not easier.

    I’ve been working with these AI coding assistants on day-to-day work — the boring-but-necessary bits as much as the clever ones. And the most useful thing I’ve learnt is that the marketing pages all sound the same, while the tools themselves really don’t.

    So, let’s have a look. (Comparison checked against each vendor’s documentation in October 2026. These tools change monthly, so check before you commit.)

    AI coding assistants in a nutshell

    • Claude Code: an agent first. Strongest when the task spans the whole repository and needs planning.
    • Cline: open source and bring-your-own-model. Maximum control, a bit more setup.
    • Cursor: an AI-native editor. The smoothest “AI inside every keystroke” experience.
    • GitHub Copilot: the easiest to roll out. It lives where your team already works, especially if that’s GitHub.

    First, what do we mean by an AI coding assistant?

    The words get used loosely, so here’s how I’ll use them:

    • Autocomplete — the tool suggests the next line or block as you type. You stay in control of every change.
    • Chat — you ask questions about your code and paste answers in yourself.
    • Agent — the tool plans a task, edits several files, runs commands and tests, and checks its own work. You review the result.
    • MCP (Model Context Protocol) — an open standard that lets an assistant use external tools and data, such as Jira, a database or your Salesforce org.

    Here’s the shift that matters for AI coding assistants today. All four tools now offer an agent and MCP. The difference is which of those modes each tool was built around.

    Claude Code

    If you like working in a terminal and thinking in tasks rather than keystrokes, this is the one that feels most at home.

    Claude Code is Anthropic’s agentic coding tool. Despite its terminal-first reputation, Anthropic’s documentation lists five places it runs: the terminal, VS Code, JetBrains, a desktop app and the web. Your settings, project instructions and MCP servers carry across all of them.

    Built around: the agent — read the repo, plan, edit, run, verify. Models: Anthropic’s Claude models. MCP: yes, configured once and shared across every surface. Watch-outs: inline autocomplete isn’t the point. And you’re tied to one model family.

    Example scenarios

    • Refactoring a shared service used by 30 classes, with tests run after every step.
    • “Read this repo and explain how authentication works” on a codebase you inherited yesterday.

    Cline

    Cline is for people who want to see, and choose, everything.

    It’s an open-source (Apache 2.0) agent that runs as a VS Code extension. You connect your own model provider — Anthropic, OpenAI, Google, or a local model — and pay that provider directly. Its Plan mode is read-only: it explores and proposes. Act mode carries out the plan and asks for approval on risky steps like file writes and terminal commands.

    Built around: the agent, with you approving each step. Models: any provider you connect, including local ones. MCP: yes, and it’s a big part of its appeal. Watch-outs: you own the setup, the keys and the bill. A long autonomous run on an expensive model adds up fast.

    Example scenarios

    • A team with strict data rules running Cline against a self-hosted model.
    • Planning with a strong reasoning model, then switching to a cheaper one to execute.

    Cursor

    Cursor is the one people describe as “it just feels fast.”

    It’s a full code editor built on VS Code, with AI in every layer: autocomplete that predicts your next edit, chat, an agent, and background agents that work on tasks while you carry on. According to Cursor’s models and pricing page, you can use Cursor’s own models alongside Claude, GPT and Gemini, depending on your plan.

    Built around: the editor experience. Models: Cursor’s own plus the major third-party models. MCP: yes. Watch-outs: you’re switching editors, not adding an extension. Some enterprises will want a close look at governance and where code is processed.

    Example scenarios

    • A product team shipping UI changes daily, where autocomplete speed matters most.
    • Handing a well-scoped bug to a background agent while you keep coding.

    GitHub Copilot

    Copilot is the “nobody has to change anything” option. And that’s a real strength.

    It started as autocomplete. It’s now much more than that. Agent mode works inside VS Code, Visual Studio, JetBrains, Xcode and Eclipse. Copilot’s cloud agent picks up a GitHub issue and comes back with a pull request. And you can pick from OpenAI, Claude and Gemini models.

    Built around: reach — every major IDE, plus GitHub itself. Models: multiple providers, chosen per task. MCP: yes, in the IDE, the CLI and the cloud agent (admins control which servers and tools it can use). Watch-outs: the agent features are newer than the autocomplete, and some depend on your plan and on org policies being switched on.

    Example scenarios

    • A 500-developer enterprise that needs one approved tool, managed centrally.
    • Assigning a small backlog issue to Copilot and reviewing the PR it opens.

    AI coding assistants side by side

    Here’s how the four AI coding assistants compare, trimmed to the rows that actually separate them.

    Claude CodeClineCursorGitHub Copilot
    Built aroundAgentAgent with step approvalAI-native editorBroad IDE + GitHub reach
    Where it runsTerminal, VS Code, JetBrains, desktop, webVS Code (and forks)Its own VS Code-based editorVS Code, Visual Studio, JetBrains, Xcode, Eclipse, GitHub.com
    ModelsClaudeAny provider, incl. localCursor’s own + Claude, GPT, GeminiOpenAI, Claude, Gemini
    Open sourceNoYes (Apache 2.0)NoNo
    Inline autocompleteNot its focusNot its focusCore strengthCore strength
    Multi-file agent workCore strengthCore strengthStrongStrong, and improving
    Tasks in the cloudYes (web)No, runs locallyYes (background agents)Yes (cloud agent from issues)
    MCPYesYesYesYes
    How you payClaude plan or API usageYour model providerCursor plansCopilot plans
    Easiest winLarge, planning-heavy changesControl over models and costSpeed while typingRollout to a whole team
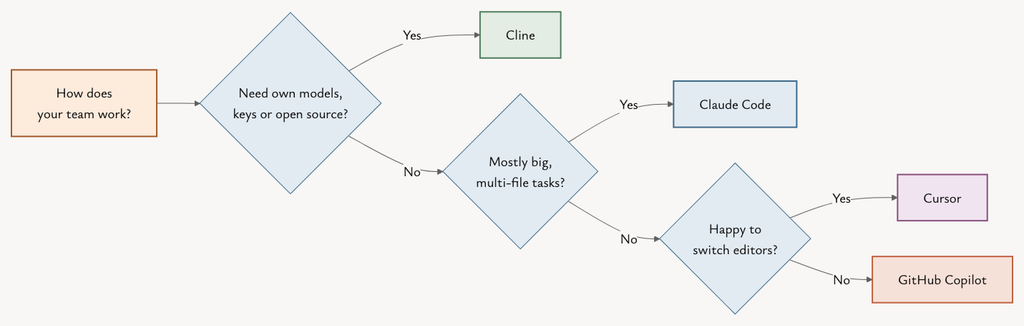
    Decision flow for choosing between AI coding assistants Claude Code, Cline, Cursor and GitHub Copilot
    Which AI coding assistant fits you? Start with how you work, not with the feature list.

    And what about Salesforce developers?

    This is where it gets interesting for most people reading this blog.

    Salesforce publishes a Salesforce DX MCP Server that understands the content and configuration of your DX project. Salesforce also describes a hosted MCP option that runs on Salesforce infrastructure with per-user OAuth. Because all four tools support MCP, any of these AI coding assistants can now work with Apex, LWC and your org metadata with real context instead of guesswork.

    Salesforce also has its own option, Agentforce Vibes, which runs in VS Code-compatible editors and generates Apex and Lightning Web Components.

    A few things I’d insist on before anyone points an agent at an org:

    • Sandboxes, not production. An agent that can deploy will eventually deploy something you didn’t expect.
    • Least-privilege access. Allowlist read-only MCP tools first. GitHub’s own docs recommend exactly this for its cloud agent.
    • Same review gates. Agent-written Apex still goes through code review, tests and your deployment pipeline. No shortcuts.

    So, what’s the honest verdict?

    Here’s the question everyone asks:

    “Which AI coding assistant is the best?”

    And here’s the one worth asking:

    “Which one is best for the way my team works?”

    1. Do you want to change editors?

    If not, Copilot or Claude Code (via its extensions) will fit in. If you’re happy to switch, Cursor rewards it.

    2. How much of your work is “big task” vs “next line”?

    Planning-heavy, multi-file changes favour Claude Code and Cline. Fast, continuous editing favours Cursor and Copilot.

    3. Who controls the models and the bill?

    If you need your own keys, local models or open source, that’s Cline. Everyone else trades some control for convenience.

    4. What will your security team sign off?

    Copilot has the easiest enterprise story for GitHub shops. For the others, check where code is processed and what the admin controls cover.

    If a client asked me tomorrow which AI coding assistants to roll out, I’d say this. Roll out Copilot or Claude Code as the team default. Give the developers who do the heavy architecture and refactoring work an agent-first tool. And let your power users experiment with Cline. I’d expect most teams to end up running two of these, not one.

    The bigger picture

    These AI coding assistants are converging. Every one of them now reads whole repositories, edits multiple files, runs commands and plugs into MCP.

    So the differences that will matter next year aren’t features. They’re how much autonomy you’re comfortable with, how well the tool fits your governance, and what it costs per finished task — not per seat.

    Which brings us back to the question we started with. Which tool is best?

    Well… which job are we talking about?

    If you’re interested in how Salesforce is putting AI to work on the marketing side, have a look at Smart features in the new Marketing Cloud Next. And if you’re weighing up these tools for a Salesforce team, do get in touch.